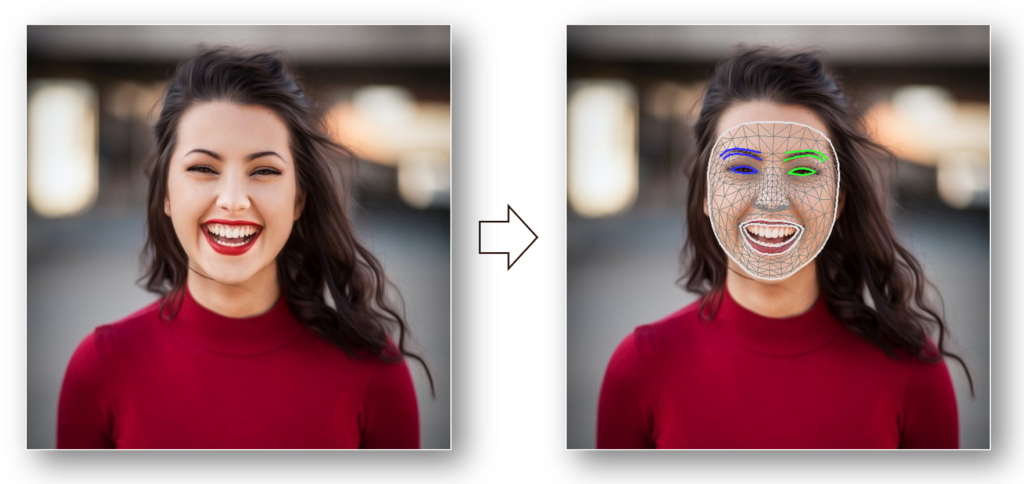
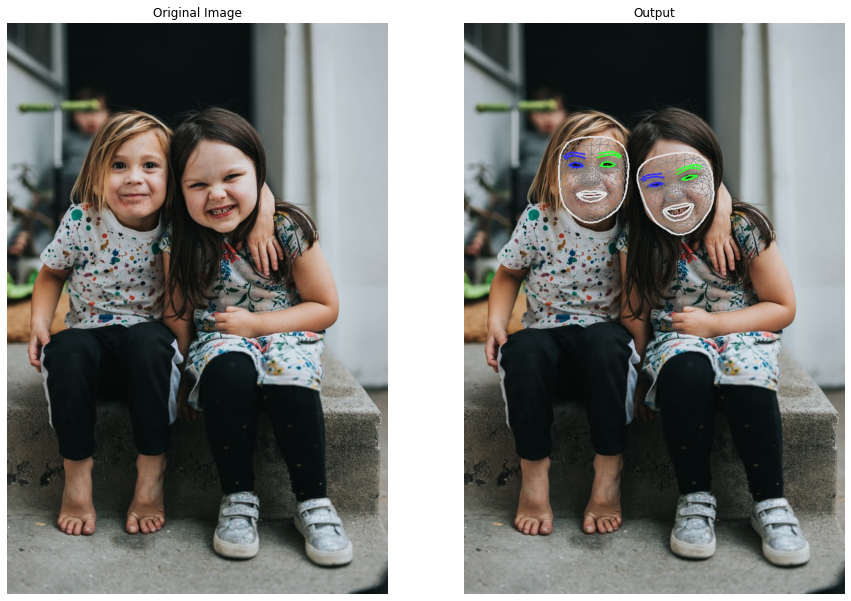
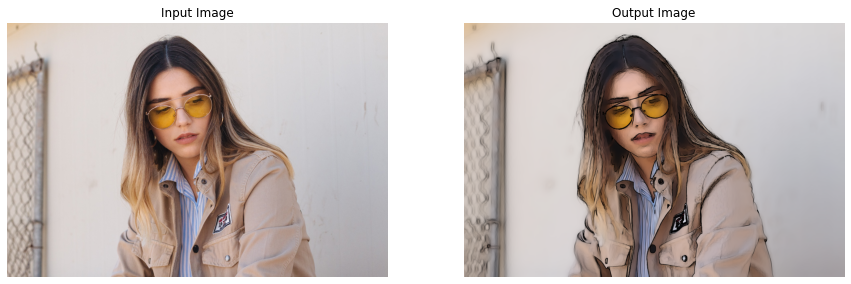
In this tutorial, we’ll learn to perform real-time multi-face detection followed by 3D face landmarks detection using the Mediapipe library in python on 2D images/videos, without using any dedicated depth sensor. After that, we will learn to build a facial expression recognizer that tells you if the person’s eyes or mouth are open or closed
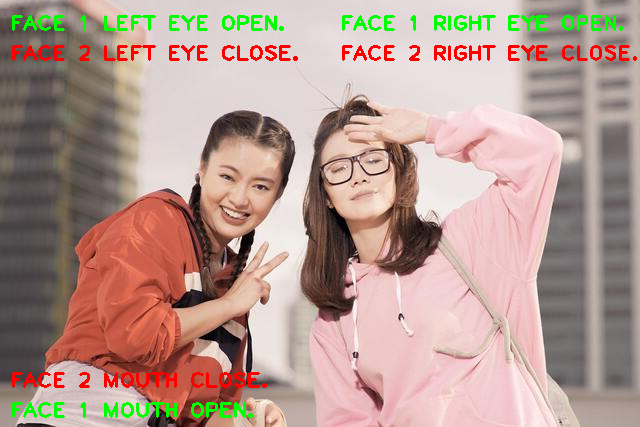
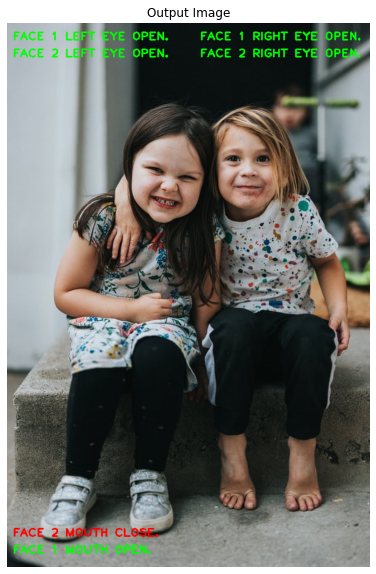
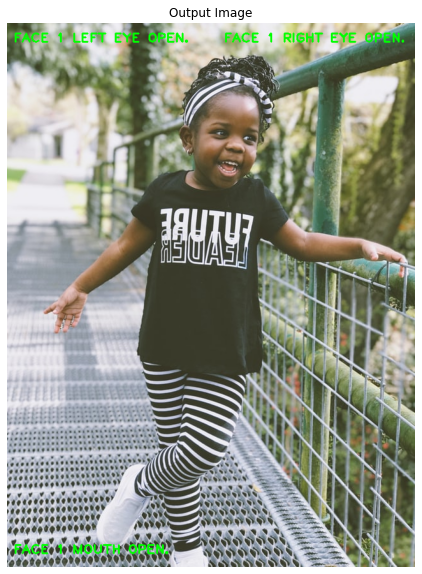
Below you can see the facial expression recognizer in action, on a few sample images:
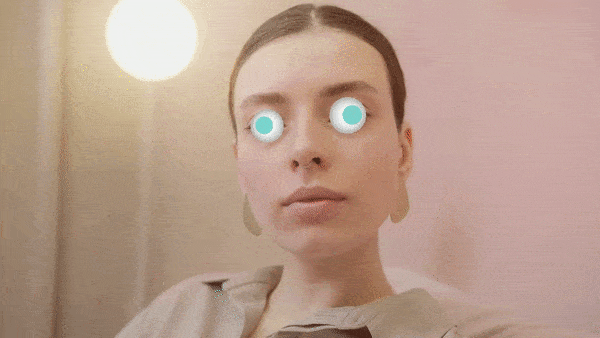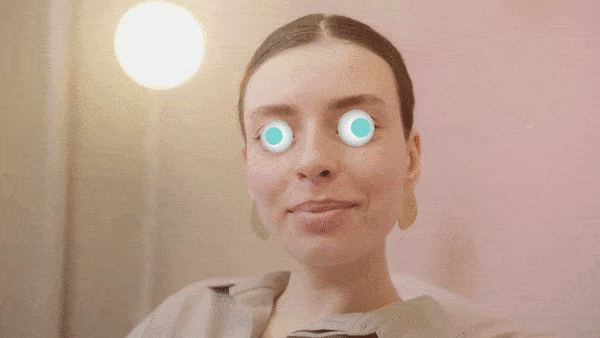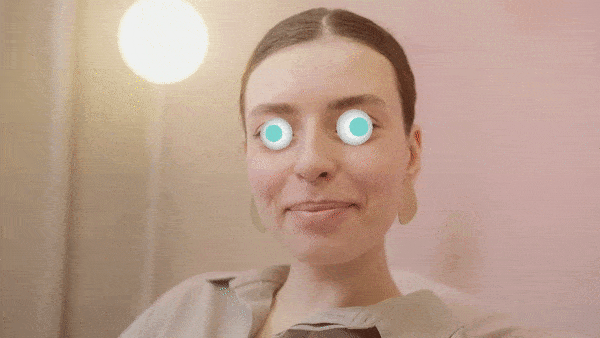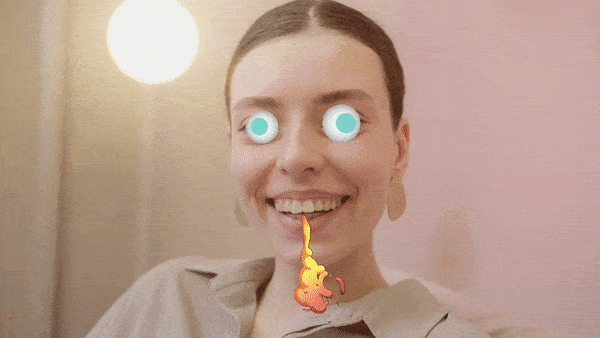
And then, in the end, we see how we can combine what we’ve learned to create animated Snapchat-like 2d filters and overlay them over the faces in images and videos. The filters will trigger in real-time for videos based on the facial expressions of the person. Below you can see results on a sample video.
Everything that we will build will work on the images, camera feed in real-time, and recorded videos as well, and the code is very neatly structured and is explained in the simplest manner possible.
This tutorial also has a video version that you can go and watch for a detailed explanation, although this blog post alone can also suffice.
Part 1 (a): Introduction to Face Landmarks Detection
Facial landmark detection/estimation is the process of detecting and tracking face key landmarks (that represent important regions of the face e.g, the center of the eye, and the tip of the nose, etc) in images and videos. It allows you to localize the face features and identify the shape and orientation of the face.
Part 1 (b): Mediapipe’s Face Landmarks Detection Implementation
If Here’s a brief introduction to Mediapipe;
“Mediapipe is a cross-platform/open-source tool that allows you to run a variety of machine learning models in real-time. It’s designed primarily for facilitating the use of ML in streaming media & It was built by Google”
All the solutions provided by Mediapipe are state-of-the-art in terms of speed and accuracy and are used in a lot of well-known applications.
The facial landmarks detection solution provided by Mediapipe is capable of detecting 3D 468 facial landmarks from a 2D image/video and is pretty fast and highly accurate as well and even works fine for occluded faces in varying lighting conditions and with faces of various orientations, and sizes in real-time, even on low-end devices like mobile phones, and Raspberry Pi, etc.
The landmarks detector’s remarkable speed distinguishes it from the other solutions out there anThe landmarks detector’s remarkable speed distinguishes it from the other solutions out there and the reason which makes this solution so fast is that they are using a 2 step detection approach where they have combined a face detector with a comparatively less computationally expensive tracker
So that for the videos, the tracker can be used instead of invoking the face detector at every frame. Let’s dive further into more details
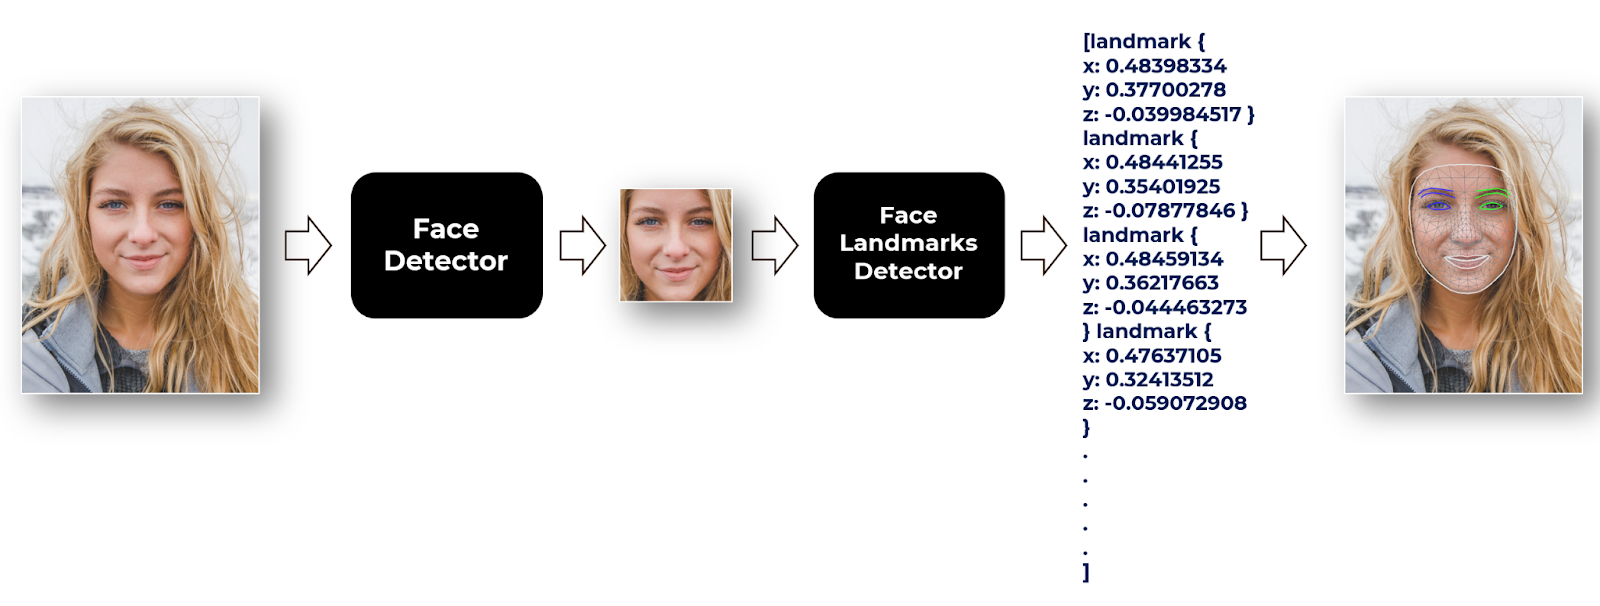
The machine learning pipeline of the Mediapipe’s solution contains two different models that work together:
A face detector that operates on the full image and locates the faces in the image.
A face landmarks detector that operates only on those face locations and predicts the 3D facial landmarks.
So the landmarks detector gets an accurately cropped face ROI which makes it capable of precisely working on scaled, rotated, and translated faces without needing data augmentation techniques.
In addition, the faces can also be located based on the face landmarks identified in the previous frame, so the face detector is only invoked as needed, that is in the very first frame or when the tracker loses track of any of the faces.
They have utilized transfer learning and used both synthetic rendered and annotated real-world data to get a model capable of predicting 3D landmark coordinates. Another approach could be to train a model to predict a 2D heatmap for each landmark but will increase the computational cost as there are so many points.
Alright now we have gone through the required basic theory and implementation details of the solution provided by Mediapipe, so without further ado, let’s get started with the code.
Download Code:
[optin-monster slug=”pcj5qsilaajmf3fnkrnm”]
Part 2: Face Landmarks Detection on images and videos
Import the Libraries
Let’s start by importing the required libraries.
import cv2
import itertools
import numpy as np
from time import time
import mediapipe as mp
import matplotlib.pyplot as plt
As mentioned Mediapipe’s face landmarks detection solution internally uses a face detector to get the required Regions of Interest (faces) from the image. So before going to the facial landmarks detection, let’s briefly discuss that face detector first, as Mediapipe also allows to separately use it.
Face Detection
The mediapipe’s face detection solution is based on BlazeFace face detector that uses a very lightweight and highly accurate feature extraction network, that is inspired and modified from MobileNetV1/V2 and used a detection method similar to Single Shot MultiBox Detector (SSD). It is capable of running at a speed of 200-1000+ FPS on flagship devices. For more info, you can check the resources here.
Initialize the Mediapipe Face Detection Model
To use the Mediapipe’s Face Detection solution, we will first have to initialize the face detection class using the syntax mp.solutions.face_detection, and then we will have to call the function mp.solutions.face_detection.FaceDetection() with the arguments explained below:
model_selection – It is an integer index ( i.e., 0 or 1 ). When set to 0, a short-range model is selected that works best for faces within 2 meters from the camera, and when set to 1, a full-range model is selected that works best for faces within 5 meters. Its default value is 0.
min_detection_confidence – It is the minimum detection confidence between ([0.0, 1.0]) required to consider the face-detection model’s prediction successful. Its default value is 0.5 ( i.e., 50% ) which means that all the detections with prediction confidence less than 0.5 are ignored by default.
We will also have to initialize the drawing class using the syntax mp.solutions.drawing_utils which is used to visualize the detection results on the images/frames.
# Initialize the mediapipe face detection class.
mp_face_detection = mp.solutions.face_detection

# Setup the face detection function.
face_detection = mp_face_detection.FaceDetection(model_selection=0, min_detection_confidence=0.5)

# Initialize the mediapipe drawing class.
mp_drawing = mp.solutions.drawing_utils
Read an Image
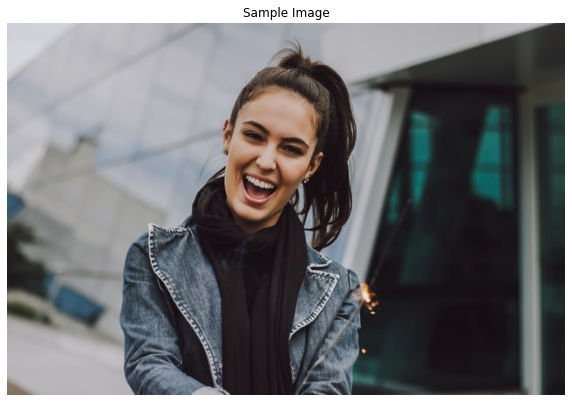
Now we will use the function cv2.imread() to read a sample image and then display the image using the matplotlib library, after converting it into RGB from BGR format.
# Read an image from the specified path.
sample_img = cv2.imread('media/sample.jpg')

# Specify a size of the figure.
plt.figure(figsize = [10, 10])

# Display the sample image, also convert BGR to RGB for display.
plt.title("Sample Image");plt.axis('off');plt.imshow(sample_img[:,:,::-1]);plt.show()
Perform Face Detection
Now to perform the detection on the sample image, we will have to pass the image (in RGB format) into the loaded model by using the function mp.solutions.face_detection.FaceDetection().process() and we will get an object that will have an attribute detections that contains a list of a bounding box and six key points for each face in the image. The six key points are on the:
Right Eye
Left Eye
Nose Tip
Mouth Center
Right Ear Tragion
Left Ear Tragion
After performing the detection, we will display the bounding box coordinates and only the first two key points of each detected face in the image, so that you get more intuition about the format of the output.
# Perform face detection after converting the image into RGB format.
face_detection_results = face_detection.process(sample_img[:,:,::-1])

# Check if the face(s) in the image are found.
if face_detection_results.detections:

    # Iterate over the found faces.
    for face_no, face in enumerate(face_detection_results.detections):

        # Display the face number upon which we are iterating upon.
        print(f'FACE NUMBER: {face_no+1}')
        print('---------------------------------')

        # Display the face confidence.
        print(f'FACE CONFIDENCE: {round(face.score[0], 2)}')

        # Get the face bounding box and face key points coordinates.
        face_data = face.location_data

        # Display the face bounding box coordinates.
        print(f'\nFACE BOUNDING BOX:\n{face_data.relative_bounding_box}')

        # Iterate two times as we only want to display first two key points of each detected face.
        for i in range(2):

            # Display the found normalized key points.
            print(f'{mp_face_detection.FaceKeyPoint(i).name}:')
            print(f'{face_data.relative_keypoints[mp_face_detection.FaceKeyPoint(i).value]}')
FACE NUMBER: 1
—————————–
FACE CONFIDENCE: 0.98
FACE BOUNDING BOX:
xmin: 0.39702364802360535
ymin: 0.2762746810913086
width: 0.16100731492042542
height: 0.24132275581359863
RIGHT_EYE:
x: 0.4368540048599243
y: 0.3198586106300354
LEFT_EYE:
x: 0.5112437605857849
y: 0.3565130829811096
Note:The bounding boxes are composed of xmin and width (both normalized to [0.0, 1.0] by the image width) and ymin and height (both normalized to [0.0, 1.0] by the image height). Each keypoint is composed of x and y, which are normalized to [0.0, 1.0] by the image width and height respectively.
Now we will draw the detected bounding box(es) and the key points on a copy of the sample image using the function mp.solutions.drawing_utils.draw_detection() from the class mp.solutions.drawing_utils, we had initialized earlier and will display the resultant image using the matplotlib library.
# Create a copy of the sample image to draw the bounding box and key points.
img_copy = sample_img[:,:,::-1].copy()

# Check if the face(s) in the image are found.
if face_detection_results.detections:

    # Iterate over the found faces.
    for face_no, face in enumerate(face_detection_results.detections):

        # Draw the face bounding box and key points on the copy of the sample image.
        mp_drawing.draw_detection(image=img_copy, detection=face,
                                 keypoint_drawing_spec=mp_drawing.DrawingSpec(color=(255, 0, 0),
                                                                              thickness=2,
                                                                              circle_radius=2))
# Specify a size of the figure.
fig = plt.figure(figsize = [10, 10])

# Display the resultant image with the bounding box and key points drawn,
# also convert BGR to RGB for display.
plt.title("Resultant Image");plt.axis('off');plt.imshow(img_copy);plt.show()
Note:Although, the detector quite accurately detects the faces, but fails to precisely detect facial key points (landmarks) in some scenarios (e.g. for non-frontal, rotated, or occluded faces) so that is why we will need the Mediapipe’s face landmarks detection solution for creating the Snapchat filter that is our main goal.
Face Landmarks Detection
Now, let’s move to the facial landmarks detection, we will start by initializing the face landmarks detection model.
Initialize the Mediapipe Face Landmarks Detection Model
To initialize the Mediapipe’s face landmarks detection model, we will have to initialize the face mesh class using the syntax mp.solutions.face_mesh and then we will have to call the function mp.solutions.face_mesh.FaceMesh() with the arguments explained below:
static_image_mode – It is a boolean value that is if set to False, the solution treats the input images as a video stream. It will try to detect faces in the first input images, and upon a successful detection further localizes the face landmarks. In subsequent images, once all max_num_faces faces are detected and the corresponding face landmarks are localized, it simply tracks those landmarks without invoking another detection until it loses track of any of the faces. This reduces latency and is ideal for processing video frames. If set to True, face detection runs on every input image, ideal for processing a batch of static, possibly unrelated, images. Its default value is False.
max_num_faces – It is the maximum number of faces to detect. Its default value is 1.
min_detection_confidence – It is the minimum detection confidence ([0.0, 1.0]) required to consider the face-detection model’s prediction correct. Its default value is 0.5 which means that all the detections with prediction confidence less than 50% are ignored by default.
min_tracking_confidence – It is the minimum tracking confidence ([0.0, 1.0]) from the landmark-tracking model for the face landmarks to be considered tracked successfully, or otherwise face detection will be invoked automatically on the next input image, so increasing its value increases the robustness, but also increases the latency. It is ignored if static_image_mode is True, where face detection simply runs on every image. Its default value is 0.5.
After that, we will initialize the mp.solutions.drawing_styles class that will allow us to get different provided drawing styles of the landmarks on the images/frames.
# Initialize the mediapipe face mesh class.
mp_face_mesh = mp.solutions.face_mesh

# Setup the face landmarks function for images.
face_mesh_images = mp_face_mesh.FaceMesh(static_image_mode=True, max_num_faces=2,
                                         min_detection_confidence=0.5)

# Setup the face landmarks function for videos.
face_mesh_videos = mp_face_mesh.FaceMesh(static_image_mode=False, max_num_faces=1,
                                         min_detection_confidence=0.5,min_tracking_confidence=0.3)

# Initialize the mediapipe drawing styles class.
mp_drawing_styles = mp.solutions.drawing_styles
Perform Face Landmarks Detection
Now to perform the landmarks detection, we will pass the image (in RGB format) to the face landmarks detection machine learning pipeline by using the function mp.solutions.face_mesh.FaceMesh().process() and get a list of four hundred sixty-eight facial landmarks for each detected face in the image. Each landmark will have:
x – It is the landmark x-coordinate normalized to [0.0, 1.0] by the image width.
y – It is the landmark y-coordinate normalized to [0.0, 1.0] by the image height.
z – It is the landmark z-coordinate normalized to roughly the same scale as x. It represents the landmark depth with the center of the head being the origin, and the smaller the value is, the closer the landmark is to the camera.
We will display only two landmarks of each eye to get an intuition about the format of output, the ml pipeline outputs an object that has an attribute multi_face_landmarks that contains the found landmarks coordinates of each face as an element of a list.
# Perform face landmarks detection after converting the image into RGB format.
face_mesh_results = face_mesh_images.process(sample_img[:,:,::-1])

# Get the list of indexes of the left and right eye.
LEFT_EYE_INDEXES = list(set(itertools.chain(*mp_face_mesh.FACEMESH_LEFT_EYE)))
RIGHT_EYE_INDEXES = list(set(itertools.chain(*mp_face_mesh.FACEMESH_RIGHT_EYE)))

# Check if facial landmarks are found.
if face_mesh_results.multi_face_landmarks:

    # Iterate over the found faces.
    for face_no, face_landmarks in enumerate(face_mesh_results.multi_face_landmarks):

        # Display the face number upon which we are iterating upon.
        print(f'FACE NUMBER: {face_no+1}')
        print('-----------------------')

        # Display the face part name i.e., left eye whose landmarks we are gonna display.
        print(f'LEFT EYE LANDMARKS:\n')

        # Iterate over the first two landmarks indexes of the left eye.
        for LEFT_EYE_INDEX in LEFT_EYE_INDEXES[:2]:

            # Display the found normalized landmarks of the left eye.
            print(face_landmarks.landmark[LEFT_EYE_INDEX])

        # Display the face part name i.e., right eye whose landmarks we are gonna display.
        print(f'RIGHT EYE LANDMARKS:\n')

        # Iterate over the first two landmarks indexes of the right eye.
        for RIGHT_EYE_INDEX in RIGHT_EYE_INDEXES[:2]:

            # Display the found normalized landmarks of the right eye.
            print(face_landmarks.landmark[RIGHT_EYE_INDEX])
Note:The z-coordinate is just the relative distance of the landmark from the center of the head, and this distance increases and decreases depending upon the distance from the camera so that is why it represents the depth of each landmark point.
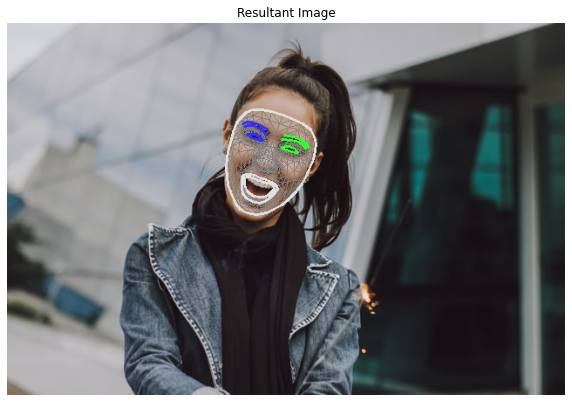
Now we will draw the detected landmarks on a copy of the sample image using the function mp.solutions.drawing_utils.draw_landmarks() from the classmp.solutions.drawing_utils, we had initialized earlier and will display the resultant image. The function mp.solutions.drawing_utils.draw_landmarks() can take the following arguments.
image – It is the image in RGB format on which the landmarks are to be drawn.
landmark_list – It is the normalized landmark list that is to be drawn on the image.
connections – It is the list of landmark index tuples that specifies how landmarks to be connected in the drawing. The provided options are; mp_face_mesh.FACEMESH_FACE_OVAL, mp_face_mesh.FACEMESH_LEFT_EYE, mp_face_mesh.FACEMESH_LEFT_EYEBROW, mp_face_mesh.FACEMESH_LIPS, mp_face_mesh.FACEMESH_RIGHT_EYE, mp_face_mesh.FACEMESH_RIGHT_EYEBROW, mp_face_mesh.FACEMESH_TESSELATION, mp_face_mesh.FACEMESH_CONTOURS.
landmark_drawing_spec – It specifies the landmarks’ drawing settings such as color, line thickness, and circle radius. It can be set equal to the mp.solutions.drawing_utils.DrawingSpec(color, thickness, circle_radius)) object.
connection_drawing_spec – It specifies the connections’ drawing settings such as color and line thickness. It can be either a mp.solutions.drawing_utils.DrawingSpec object or a function from the class mp.solutions.drawing_styles, the currently provided options for face mesh are; get_default_face_mesh_contours_style() ,get_default_face_mesh_tesselation_style().
# Create a copy of the sample image in RGB format to draw the found facial landmarks on.
img_copy = sample_img[:,:,::-1].copy()

# Check if facial landmarks are found.
if face_mesh_results.multi_face_landmarks:

    # Iterate over the found faces.
    for face_landmarks in face_mesh_results.multi_face_landmarks:

        # Draw the facial landmarks on the copy of the sample image with the
        # face mesh tesselation connections using default face mesh tesselation style.
        mp_drawing.draw_landmarks(image=img_copy,
                                  landmark_list=face_landmarks,connections=mp_face_mesh.FACEMESH_TESSELATION,
                                  landmark_drawing_spec=None,
                                  connection_drawing_spec=mp_drawing_styles.get_default_face_mesh_tesselation_style())

        # Draw the facial landmarks on the copy of the sample image with the
        # face mesh contours connections using default face mesh contours style.
        mp_drawing.draw_landmarks(image=img_copy, landmark_list=face_landmarks,connections=mp_face_mesh.FACEMESH_CONTOURS,
                                  landmark_drawing_spec=None,
                                  connection_drawing_spec=mp_drawing_styles.get_default_face_mesh_contours_style())

# Specify a size of the figure.
fig = plt.figure(figsize = [10, 10])

# Display the resultant image with the face mesh drawn.
plt.title("Resultant Image");plt.axis('off');plt.imshow(img_copy);plt.show()
Create a Face Landmarks Detection Function
Now we will put all this together to create a function detectFacialLandmarks() that will perform face landmarks detection on an image and will visualize the resultant image along with the original image or return the resultant image along with the output of the model depending upon the passed arguments.
def detectFacialLandmarks(image, face_mesh, display = True):
    '''
    This function performs facial landmarks detection on an image.
    Args:
        image:     The input image of person(s) whose facial landmarks needs to be detected.
        face_mesh: The face landmarks detection function required to perform the landmarks detection.
        display:   A boolean value that is if set to true the function displays the original input image,
                   and the output image with the face landmarks drawn and returns nothing.
    Returns:
        output_image: A copy of input image with face landmarks drawn.
        results:      The output of the facial landmarks detection on the input image.
    '''

    # Perform the facial landmarks detection on the image, after converting it into RGB format.
    results = face_mesh.process(image[:,:,::-1])

    # Create a copy of the input image to draw facial landmarks.
    output_image = image[:,:,::-1].copy()

    # Check if facial landmarks in the image are found.
    if results.multi_face_landmarks:

        # Iterate over the found faces.
        for face_landmarks in results.multi_face_landmarks:

            # Draw the facial landmarks on the output image with the face mesh tesselation
            # connections using default face mesh tesselation style.
            mp_drawing.draw_landmarks(image=output_image, landmark_list=face_landmarks,
                                      connections=mp_face_mesh.FACEMESH_TESSELATION,
                                      landmark_drawing_spec=None,
                                      connection_drawing_spec=mp_drawing_styles.get_default_face_mesh_tesselation_style())

            # Draw the facial landmarks on the output image with the face mesh contours
            # connections using default face mesh contours style.
            mp_drawing.draw_landmarks(image=output_image, landmark_list=face_landmarks,
                                      connections=mp_face_mesh.FACEMESH_CONTOURS,
                                      landmark_drawing_spec=None,
                                      connection_drawing_spec=mp_drawing_styles.get_default_face_mesh_contours_style())

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Original Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image);plt.title("Output");plt.axis('off');

    # Otherwise
    else:

        # Return the output image in BGR format and results of facial landmarks detection.
        return np.ascontiguousarray(output_image[:,:,::-1], dtype=np.uint8), results
Now we will utilize the function detectFacialLandmarks() created above to perform face landmarks detection on a few sample images and display the results.
# Read a sample image and perform facial landmarks detection on it.
image = cv2.imread('media/sample1.jpg')
detectFacialLandmarks(image, face_mesh_images, display=True)
# Read another sample image and perform facial landmarks detection on it.
image = cv2.imread('media/sample2.jpg')
detectFacialLandmarks(image, face_mesh_images, display=True)
# Read another sample image and perform facial landmarks detection on it.
image = cv2.imread('media/sample3.jpg')
detectFacialLandmarks(image, face_mesh_images, display=True)
Face Landmarks Detection on Real-Time Webcam Feed
The results on the images were remarkable, but now we will try the function on a real-time webcam feed. We will also calculate and display the number of frames being updated in one second to get an idea of whether this solution can work in real-time on a CPU or not.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)

# Create named window for resizing purposes.
cv2.namedWindow('Face Landmarks Detection', cv2.WINDOW_NORMAL)

# Initialize a variable to store the time of the previous frame.
time1 = 0

# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():

    # Read a frame.
    ok, frame = camera_video.read()

    # Check if frame is not read properly then continue to the next iteration to
    # read the next frame.
    if not ok:
        continue

    # Flip the frame horizontally for natural (selfie-view) visualization.
    frame = cv2.flip(frame, 1)

    # Perform Face landmarks detection.
    frame, _ = detectFacialLandmarks(frame, face_mesh_videos, display=False)

    # Set the time for this frame to the current time.
    time2 = time()

    # Check if the difference between the previous and this frame time > 0 to avoid
    # division by zero.
    if (time2 - time1) > 0:

        # Calculate the number of frames per second.
        frames_per_second = 1.0 / (time2 - time1)

        # Write the calculated number of frames per second on the frame.
        cv2.putText(frame, 'FPS: {}'.format(int(frames_per_second)), (10, 30),
                    cv2.FONT_HERSHEY_PLAIN, 2, (0, 255, 0), 3)

    # Update the previous frame time to this frame time.
    # As this frame will become previous frame in next iteration.
    time1 = time2

    # Display the frame.
    cv2.imshow('Face Landmarks Detection', frame)

    # Wait for 1ms. If a key is pressed, retreive the ASCII code of the key.
    k = cv2.waitKey(1) & 0xFF

    # Check if 'ESC' is pressed and break the loop.
    if(k == 27):
        break

# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output
Impressive! the solution is fast as well as accurate.
Face Expression Recognition
Now that we have the detected landmarks, we will use them to recognize the facial expressions of people in the images/videos using the classical techniques. Our recognizor will be capable of identifying the following facial expressions:
Eyes Opened or Closed 😳 (can be used to check drowsiness, wink or shock expression)
Mouth Opened or Closed 😱 (can be used to check yawning)
For the sake of simplicity, we are only limiting this to two expressions. But if you want, you can easily extend this application to make it capable of identifying more facial expressions just by adding more conditional statements or maybe merging these two conditions. Like for example, eyes and mouth both wide open can represent surprise expression.
Create a Function to Calculate Size of a Face Part
First, we will create a function getSize() that will utilize detected landmarks to calculate the size of a face part. All we will need is to figure out a way to isolate the landmarks of the face part and luckily that can easily be done using the frozenset objects (attributes of the mp.solutions.face_mesh class), which contain the required indexes.
mp_face_mesh.FACEMESH_FACE_OVAL contains indexes of face outline.
mp_face_mesh.FACEMESH_LIPS contains indexes of lips.
mp_face_mesh.FACEMESH_LEFT_EYE contains indexes of left eye.
mp_face_mesh.FACEMESH_RIGHT_EYE contains indexes of right eye.
mp_face_mesh.FACEMESH_LEFT_EYEBROW contains indexes of left eyebrow.
mp_face_mesh.FACEMESH_RIGHT_EYEBROW contains indexes of right eyebrow.
After retrieving the landmarks of the face part, we will simply pass it to the function cv2.boundingRect() to get the width and height of the face part. The function cv2.boundingRect(landmarks) returns the coordinates (x1, y1, width, height) of a bounding box enclosing the object (face part), given the landmarks but we will only need the height and width of the bounding box.
def getSize(image, face_landmarks, INDEXES):
    '''
    This function calculate the height and width of a face part utilizing its landmarks.
    Args:
        image:          The image of person(s) whose face part size is to be calculated.
        face_landmarks: The detected face landmarks of the person whose face part size is to
                        be calculated.
        INDEXES:        The indexes of the face part landmarks, whose size is to be calculated.
    Returns:
        width:     The calculated width of the face part of the face whose landmarks were passed.
        height:    The calculated height of the face part of the face whose landmarks were passed.
        landmarks: An array of landmarks of the face part whose size is calculated.
    '''

    # Retrieve the height and width of the image.
    image_height, image_width, _ = image.shape

    # Convert the indexes of the landmarks of the face part into a list.
    INDEXES_LIST = list(itertools.chain(*INDEXES))

    # Initialize a list to store the landmarks of the face part.
    landmarks = []

    # Iterate over the indexes of the landmarks of the face part.
    for INDEX in INDEXES_LIST:

        # Append the landmark into the list.
        landmarks.append([int(face_landmarks.landmark[INDEX].x * image_width),
                               int(face_landmarks.landmark[INDEX].y * image_height)])

    # Calculate the width and height of the face part.
    _, _, width, height = cv2.boundingRect(np.array(landmarks))

    # Convert the list of landmarks of the face part into a numpy array.
    landmarks = np.array(landmarks)

    # Retrurn the calculated width height and the landmarks of the face part.
    return width, height, landmarks
Now we will create a function isOpen() that will utilize the getSize() function we had created above to check whether a face part (e.g. mouth or an eye) of a person is opened or closed.
Hint:The height of an opened mouth or eye will be greater than the height of a closed mouth or eye.
def isOpen(image, face_mesh_results, face_part, threshold=5, display=True):
    '''
    This function checks whether the an eye or mouth of the person(s) is open,
    utilizing its facial landmarks.
    Args:
        image:             The image of person(s) whose an eye or mouth is to be checked.
        face_mesh_results: The output of the facial landmarks detection on the image.
        face_part:         The name of the face part that is required to check.
        threshold:         The threshold value used to check the isOpen condition.
        display:           A boolean value that is if set to true the function displays
                           the output image and returns nothing.
    Returns:
        output_image: The image of the person with the face part is opened  or not status written.
        status:       A dictionary containing isOpen statuses of the face part of all the
                      detected faces.
    '''

    # Retrieve the height and width of the image.
    image_height, image_width, _ = image.shape

    # Create a copy of the input image to write the isOpen status.
    output_image = image.copy()

    # Create a dictionary to store the isOpen status of the face part of all the detected faces.
    status={}

    # Check if the face part is mouth.
    if face_part == 'MOUTH':

        # Get the indexes of the mouth.
        INDEXES = mp_face_mesh.FACEMESH_LIPS

        # Specify the location to write the is mouth open status.
        loc = (10, image_height - image_height//40)

        # Initialize a increment that will be added to the status writing location,
        # so that the statuses of two faces donot overlap.
        increment=-30

    # Check if the face part is left eye.
    elif face_part == 'LEFT EYE':

        # Get the indexes of the left eye.
        INDEXES = mp_face_mesh.FACEMESH_LEFT_EYE

        # Specify the location to write the is left eye open status.
        loc = (10, 30)

        # Initialize a increment that will be added to the status writing location,
        # so that the statuses of two faces donot overlap.
        increment=30

    # Check if the face part is right eye.
    elif face_part == 'RIGHT EYE':

        # Get the indexes of the right eye.
        INDEXES = mp_face_mesh.FACEMESH_RIGHT_EYE

        # Specify the location to write the is right eye open status.
        loc = (image_width-300, 30)

        # Initialize a increment that will be added to the status writing location,
        # so that the statuses of two faces donot overlap.
        increment=30

    # Otherwise return nothing.
    else:
        return

    # Iterate over the found faces.
    for face_no, face_landmarks in enumerate(face_mesh_results.multi_face_landmarks):

         # Get the height of the face part.
        _, height, _ = getSize(image, face_landmarks, INDEXES)

         # Get the height of the whole face.
        _, face_height, _ = getSize(image, face_landmarks, mp_face_mesh.FACEMESH_FACE_OVAL)

        # Check if the face part is open.
        if (height/face_height)*100 > threshold:

            # Set status of the face part to open.
            status[face_no] = 'OPEN'

            # Set color which will be used to write the status to green.
            color=(0,255,0)

        # Otherwise.
        else:
            # Set status of the face part to close.
            status[face_no] = 'CLOSE'

            # Set color which will be used to write the status to red.
            color=(0,0,255)

        # Write the face part isOpen status on the output image at the appropriate location.
        cv2.putText(output_image, f'FACE {face_no+1} {face_part} {status[face_no]}.',
                    (loc[0],loc[1]+(face_no*increment)), cv2.FONT_HERSHEY_PLAIN, 1.4, color, 2)

    # Check if the output image is specified to be displayed.
    if display:

        # Display the output image.
        plt.figure(figsize=[10,10])
        plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise
    else:

        # Return the output image and the isOpen statuses of the face part of each detected face.
        return output_image, status
Now we will utilize the function isOpen() created above to check the mouth and eyes status on a few sample images and display the results.
# Read another sample image and perform facial expression recognition on it.
image = cv2.imread('media/sample1.jpg')
image = cv2.flip(image, 1)
_, face_mesh_results = detectFacialLandmarks(image, face_mesh_images, display=False)
if face_mesh_results.multi_face_landmarks:
    output_image, _ = isOpen(image, face_mesh_results, 'MOUTH', threshold=15, display=False)
    output_image, _ = isOpen(output_image, face_mesh_results, 'LEFT EYE', threshold=5, display=False)
    isOpen(output_image, face_mesh_results, 'RIGHT EYE', threshold=5)
# Read another sample image and perform facial expression recognition on it.
image = cv2.imread('media/sample2.jpg')
image = cv2.flip(image, 1)
_, face_mesh_results = detectFacialLandmarks(image, face_mesh_images, display=False)
if face_mesh_results.multi_face_landmarks:
    output_image, _ = isOpen(image, face_mesh_results, 'MOUTH', threshold=15, display=False)
    output_image, _ = isOpen(output_image, face_mesh_results, 'LEFT EYE', threshold=5, display=False)
    isOpen(output_image, face_mesh_results, 'RIGHT EYE', threshold=5)
# Read another sample image and perform facial expression recognition on it.
image = cv2.imread('media/sample3.jpg')
image = cv2.flip(image, 1)
_, face_mesh_results = detectFacialLandmarks(image, face_mesh_images, display=False)
if face_mesh_results.multi_face_landmarks:
    output_image, _ = isOpen(image, face_mesh_results, 'MOUTH', threshold=15, display=False)
    output_image, _ = isOpen(output_image, face_mesh_results, 'LEFT EYE', threshold=5, display=False)
    isOpen(output_image, face_mesh_results, 'RIGHT EYE', threshold=5)
As expected, the results are fascinating!
Snapchat Filter Controlled by Facial Expressions
Now that we have the face expression recognizer, let’s start building a Snapchat filter on top of it, that will be triggered based on the facial expressions of the person in real-time.
Currently, our face expression recognizer can check whether the eyes and mouth are open 😯 or not 😌 so to get the most out of it, we can overlay scalable eyes 👀 images on top of the eyes of the user when his eyes are open and a video of fire 🔥 coming out of the mouth of the user when the mouth is open.
Create a Function to Overlay the Image Filters
Now we will create a function overlay() that will apply the filters on top of the eyes and mouth of a person in images/videos utilizing the facial landmarks to locate the face parts and will also resize the filter images according to the size of the face part on which the filter images will be overlayed.
def overlay(image, filter_img, face_landmarks, face_part, INDEXES, display=True):
    '''
    This function will overlay a filter image over a face part of a person in the image/frame.
    Args:
        image:          The image of a person on which the filter image will be overlayed.
        filter_img:     The filter image that is needed to be overlayed on the image of the person.
        face_landmarks: The facial landmarks of the person in the image.
        face_part:      The name of the face part on which the filter image will be overlayed.
        INDEXES:        The indexes of landmarks of the face part.
        display:        A boolean value that is if set to true the function displays
                        the annotated image and returns nothing.
    Returns:
        annotated_image: The image with the overlayed filter on the top of the specified face part.
    '''

    # Create a copy of the image to overlay filter image on.
    annotated_image = image.copy()

    # Errors can come when it resizes the filter image to a too small or a too large size .
    # So use a try block to avoid application crashing.
    try:

        # Get the width and height of filter image.
        filter_img_height, filter_img_width, _  = filter_img.shape

        # Get the height of the face part on which we will overlay the filter image.
        _, face_part_height, landmarks = getSize(image, face_landmarks, INDEXES)

        # Specify the height to which the filter image is required to be resized.
        required_height = int(face_part_height*2.5)

        # Resize the filter image to the required height, while keeping the aspect ratio constant.
        resized_filter_img = cv2.resize(filter_img, (int(filter_img_width*
                                                         (required_height/filter_img_height)),
                                                     required_height))

        # Get the new width and height of filter image.
        filter_img_height, filter_img_width, _  = resized_filter_img.shape

        # Convert the image to grayscale and apply the threshold to get the mask image.
        _, filter_img_mask = cv2.threshold(cv2.cvtColor(resized_filter_img, cv2.COLOR_BGR2GRAY),
                                           25, 255, cv2.THRESH_BINARY_INV)

        # Calculate the center of the face part.
        center = landmarks.mean(axis=0).astype("int")

        # Check if the face part is mouth.
        if face_part == 'MOUTH':

            # Calculate the location where the smoke filter will be placed.
            location = (int(center[0] - filter_img_width / 3), int(center[1]))

        # Otherwise if the face part is an eye.
        else:

            # Calculate the location where the eye filter image will be placed.
            location = (int(center[0]-filter_img_width/2), int(center[1]-filter_img_height/2))

        # Retrieve the region of interest from the image where the filter image will be placed.
        ROI = image[location[1]: location[1] + filter_img_height,
                    location[0]: location[0] + filter_img_width]

        # Perform Bitwise-AND operation. This will set the pixel values of the region where,
        # filter image will be placed to zero.
        resultant_image = cv2.bitwise_and(ROI, ROI, mask=filter_img_mask)

        # Add the resultant image and the resized filter image.
        # This will update the pixel values of the resultant image at the indexes where
        # pixel values are zero, to the pixel values of the filter image.
        resultant_image = cv2.add(resultant_image, resized_filter_img)

        # Update the image's region of interest with resultant image.
        annotated_image[location[1]: location[1] + filter_img_height,
                        location[0]: location[0] + filter_img_width] = resultant_image

    # Catch and handle the error(s).
    except Exception as e:
        pass

    # Check if the annotated image is specified to be displayed.
    if display:

        # Display the annotated image.
        plt.figure(figsize=[10,10])
        plt.imshow(annotated_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise
    else:

        # Return the annotated image.
        return annotated_image
Snapchat Filter on Real-Time Webcam Feed
Now we will utilize the function overlay() created above to apply filters based on the facial expressions, that we will recognize utilizing the function isOpen() on a real-time webcam feed.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(2)
camera_video.set(3,1280)
camera_video.set(4,960)

# Create named window for resizing purposes.
cv2.namedWindow('Face Filter', cv2.WINDOW_NORMAL)

# Read the left and right eyes images.
left_eye = cv2.imread('media/left_eye.png')
right_eye = cv2.imread('media/right_eye.png')

# Initialize the VideoCapture object to read from the smoke animation video stored in the disk.
smoke_animation = cv2.VideoCapture('media/smoke_animation.mp4')

# Set the smoke animation video frame counter to zero.
smoke_frame_counter = 0

# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():

    # Read a frame.
    ok, frame = camera_video.read()

    # Check if frame is not read properly then continue to the next iteration to read
    # the next frame.
    if not ok:
        continue

    # Read a frame from smoke animation video
    _, smoke_frame = smoke_animation.read()

    # Increment the smoke animation video frame counter.
    smoke_frame_counter += 1

    # Check if the current frame is the last frame of the smoke animation video.
    if smoke_frame_counter == smoke_animation.get(cv2.CAP_PROP_FRAME_COUNT):

        # Set the current frame position to first frame to restart the video.
        smoke_animation.set(cv2.CAP_PROP_POS_FRAMES, 0)

        # Set the smoke animation video frame counter to zero.
        smoke_frame_counter = 0

    # Flip the frame horizontally for natural (selfie-view) visualization.
    frame = cv2.flip(frame, 1)

    # Perform Face landmarks detection.
    _, face_mesh_results = detectFacialLandmarks(frame, face_mesh_videos, display=False)

    # Check if facial landmarks are found.
    if face_mesh_results.multi_face_landmarks:

        # Get the mouth isOpen status of the person in the frame.
        _, mouth_status = isOpen(frame, face_mesh_results, 'MOUTH',
                                     threshold=15, display=False)

        # Get the left eye isOpen status of the person in the frame.
        _, left_eye_status = isOpen(frame, face_mesh_results, 'LEFT EYE',
                                        threshold=4.5 , display=False)

        # Get the right eye isOpen status of the person in the frame.
        _, right_eye_status = isOpen(frame, face_mesh_results, 'RIGHT EYE',
                                         threshold=4.5, display=False)

        # Iterate over the found faces.
        for face_num, face_landmarks in enumerate(face_mesh_results.multi_face_landmarks):

            # Check if the left eye of the face is open.
            if left_eye_status[face_num] == 'OPEN':

                # Overlay the left eye image on the frame at the appropriate location.
                frame = overlay(frame, left_eye, face_landmarks,
                                'LEFT EYE', mp_face_mesh.FACEMESH_LEFT_EYE, display=False)

            # Check if the right eye of the face is open.
            if right_eye_status[face_num] == 'OPEN':

                # Overlay the right eye image on the frame at the appropriate location.
                frame = overlay(frame, right_eye, face_landmarks,
                                'RIGHT EYE', mp_face_mesh.FACEMESH_RIGHT_EYE, display=False)

            # Check if the mouth of the face is open.
            if mouth_status[face_num] == 'OPEN':

                # Overlay the smoke animation on the frame at the appropriate location.
                frame = overlay(frame, smoke_frame, face_landmarks,
                                'MOUTH', mp_face_mesh.FACEMESH_LIPS, display=False)

    # Display the frame.
    cv2.imshow('Face Filter', frame)

    # Wait for 1ms. If a key is pressed, retreive the ASCII code of the key.
    k = cv2.waitKey(1) & 0xFF

    # Check if 'ESC' is pressed and break the loop.
    if(k == 27):
        break

# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output
Cool! I am impressed by the results now if you want, you can extend the application and add more filters like glasses, nose, and ears, etc. and use some other facial expressions to trigger those filters.
Join My Course Computer Vision For Building Cutting Edge Applications Course
The only course out there that goes beyond basic AI Applications and teaches you how to create next-level apps that utilize physics, deep learning, classical image processing, hand and body gestures. Don’t miss your chance to level up and take your career to new heights
You’ll Learn about:
Creating GUI interfaces for python AI scripts.
Creating .exe DL applications
Using a Physics library in Python & integrating it with AI
Advance Image Processing Skills
Advance Gesture Recognition with Mediapipe
Task Automation with AI & CV
Training an SVM machine Learning Model.
Creating & Cleaning an ML dataset from scratch.
Training DL models & how to use CNN’s & LSTMS.
Creating 10 Advance AI/CV Applications
& More
Whether you’re a seasoned AI professional or someone just looking to start out in AI, this is the course that will teach you, how to Architect & Build complex, real world and thrilling AI applications
Today, in this tutorial, we learned about a very common computer vision task called Face landmarks detection. First, we covered what exactly it is, along with its applications, and then we moved to the implementation details of the solution provided by Mediapipe and how it uses a 2-step (detection + tracking) pipeline to speed up the process.
After that, we performed multi-face detection and 3D face landmarks detection using Mediapipe’s solutions on images and real-time webcam feed.
Then we learned to recognize the facial expressions in the images/videos utilizing the face landmarks and after that, we learned to apply face filters, which were dynamically controlled by the facial expressions in the images/videos.
Alright here are a few limitations of our application that you should know about, the face expression recognizer we created is really basic to recognize dedicated expressions like shock, surprise. For that, you should train a DL model on top of these landmarks.
Another current limitation is that the face filters are not currently being rotated with the rotations of the faces in the images/videos. This can be overcome simply by calculating the face angle and rotating the filter images with the face angle. I am planning to cover this and a lot more in my upcoming course mentioned above.
You can reach out to me personally for a 1 on 1 consultation session in AI/computer vision regarding your project. Our talented team of vision engineers will help you every step of the way. Get on a call with me directlyhere.
Ready to seriously dive into State of the Art AI & Computer Vision? Then Sign up for these premium Courses by Bleed AI
Processing videos in OpenCV is one of the most common jobs, many people already know how to leverage the VideoCapture function in OpenCV to read from a live camera or video saved on disk.
But here’s some food for thought, do you know that you can also read other video sources e.g. read a live feed from an IP Camera (Or your phone’s Camera) or even read GIFS.
Yes, you’ll learn all about reading these sources with videoCapture in today’s tutorial and I’ll also be covering some very useful additional things like getting and setting different video properties (height, width, frame count, fps, etc), manually changing current frame position to repeatedly display the same video, and capturing different key events.
This will be an excellent tutorial to help you properly get started with video processing in OpenCV.
Alright, let’s first rewind a bit and go back to the basics, What is a video?
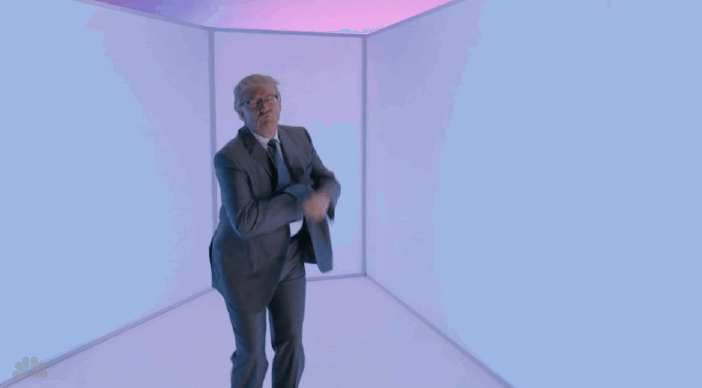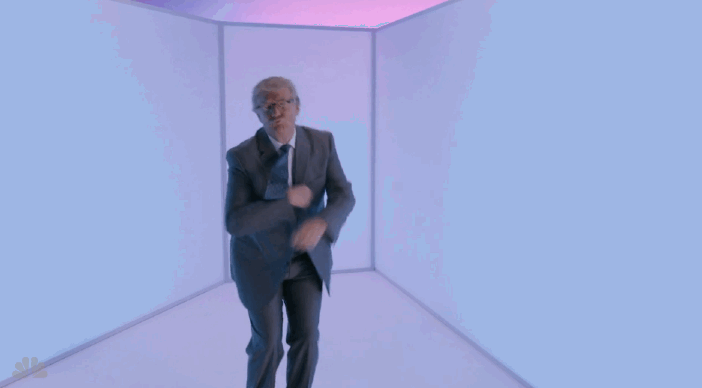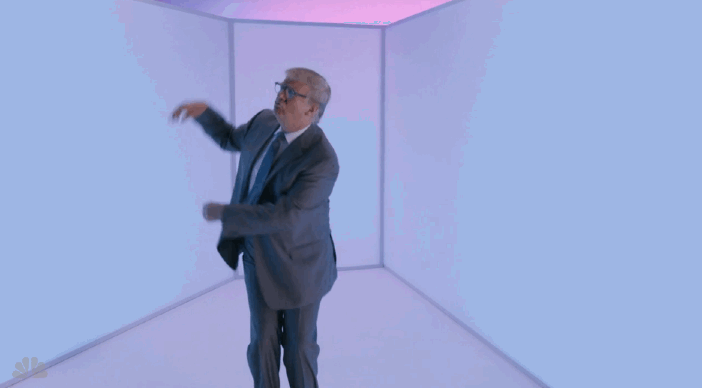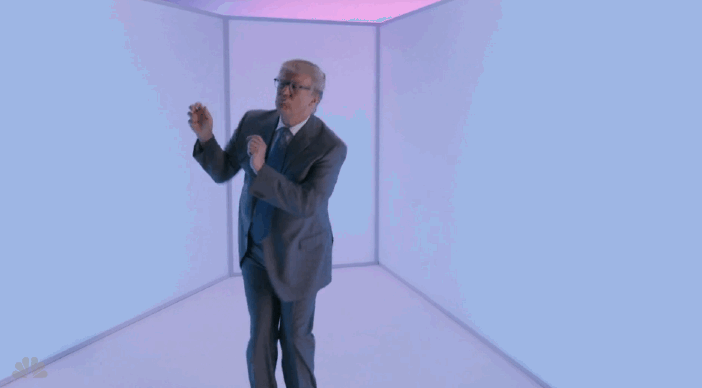
Well, it is just a sequence of multiple still images (aka. frames) that are updated really fast creating the appearance of a motion. Below you can see a combination of different still images of some guy (You know who xD) dancing.
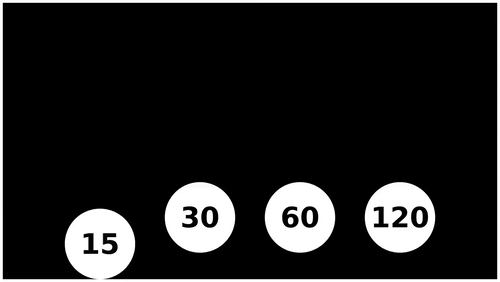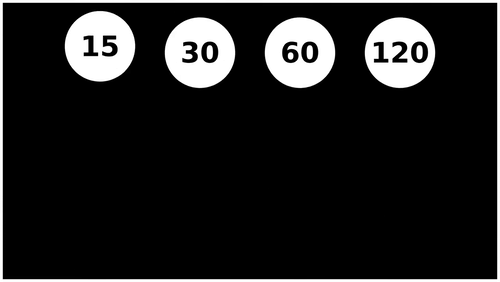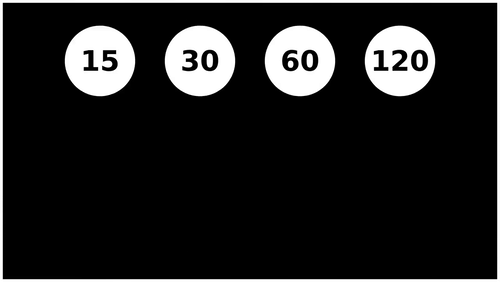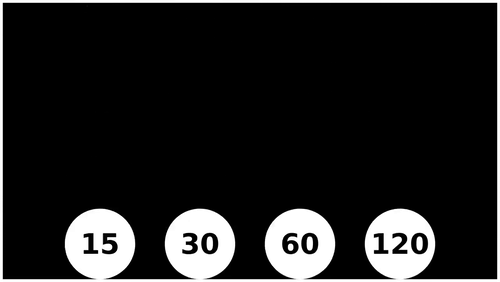
And how fast these still images are updated is measured by a metric called Frames Per Second (FPS). Different videos have different FPS and the higher the FPS, the smoother the video is. Below you can see the visualization of the smoothness in the motion of the higher FPS balls. The ball that is moving at 120 FPS has the smoothest motion, although it’s hard to tell the difference between 60fps and the 120fps ball.
Note: Consider each ball as a separate video clip.
So, a 5-second video with 15 Frames Per Second (FPS) will have a total of 75 (i.e., 15*5) frames in the whole video with each frame being updated after 60 milliseconds. While a 5-second video with 30 FPS will have 150 (i.e., 30*5) frames with each frame being updated after 30 milliseconds.
So a 30 FPS will display the same frame (still image) only for 30 milliseconds, while a 15 FPS video will display the same frame for 60 milliseconds (longer period) which will make the motion jerkier and slower and in extreme cases (< 10 FPS) may convert a video into a slideshow.
Other than FPS, there are some other properties too which determine the quality of a video like its resolution (i.e., width x height), and bitrate (i.e., amount of information in a given unit of time), etc. The higher the resolution and bitrate of a video are, the better the quality is.
This tutorial also has a video version that you can go and watch for a detailed explanation, although this blog post alone can also suffice.
Alright now we have gone through the required basic theoretical details about videos and their properties, so without further ado, let’s get started with the code.
Download Code:
[optin-monster slug=”pxnrl4t8fkursnjseege”]
Import the Libraries
We will start by importing the required libraries.
!pip install opencv-contrib-python matplotlib

import cv2
import matplotlib.pyplot as plt
from time import time
Loading a Video
To read a video, first, we will have to initialize the video capture object by using the function cv2.VideoCapture().
or Image sequence (eg. img_%02d.jpg, which will read samples like img_00.jpg, img_01.jpg, img_02.jpg, ...)
or URL of video stream (eg. protocol://host:port/script_name?script_params|auth). You can refer to the documentation of the source stream to know the right URL scheme.
index – It is the id of a video capturing device to open. To open the default camera using the default backend, you can just pass 0. In case of multiple cameras connected to the computer, you can select the second camera by passing 1, the third camera by passing 2, and so on.
apiPreference – It is the preferred capture API backend to use. Can be used to enforce a specific reader implementation if multiple are available: e.g. cv2.CAP_FFMPEG or cv2.CAP_IMAGES or cv2.CAP_DSHOW. Its default value is cv2.CAP_ANY. Check cv2.VideoCaptureAPIs for details.
Returns:
video_reader – It is the video loaded from the source specified.
So to simply put, this cv2.VideoCapture() function opens up a webcam or a video file/images sequence or an IP video stream for video capturing with API Preference. After initializing the object, we will use .isOpened() function to check if the video is accessed successfully. It returns True for success and False for failure.
# Initialized the VideoCapture object.
video_reader = cv2.VideoCapture('media/video.mp4')
# video_reader = cv2.VideoCapture(0)
# video_reader = cv2.VideoCapture('media/internet.gif')
# video_reader = cv2.VideoCapture('http://192.168.18.134:8080/video)

# Check if video is accessed.
if (video_reader.isOpened()):

    # Display the success message.
    print("Successfully accessed the video!")
else:

    # Display the failure message.
    print("Failed to access the video!")
Reading a Frame
If the video is accessed successfully, then the next step will be to read the frames of the video one by one which can be done using the function .read().
ret – It is a boolean value i.e., True if the frame is read successfully otherwise False.
frame – It is a frame/image of our video.
Note:Every time we run .read() function, it will give us a new frame i.e., the next frame of the video so we can put .read() in a loop to read all the frames of a video and the ret value is really important in such scenarios since after reading the last frame, from the video this ret will be False indicating that the video has ended.
# Read the first frame.
ret, frame = video_reader.read()

# Check if frame is read properly.
if ret:

    # Specify a size of the figure.
    plt.figure(figsize = [10, 10])

    # Display the frame, also convert BGR to RGB for display.
    plt.title('The frame read Successfully!');plt.axis('off');plt.imshow(frame[:,:,::-1]);plt.show()

else:

    # Display the failure message.
    print('Failed to read the Frame!')
Get and Set Properties of the Video
Now that we know how to read a video, we will now see how to get and set different properties of a video using the functions:
Here, propId is the Property ID and new_value is the value we want to set for the property.
Property ID
Enumerator
Property
0
cv2.CAP_PROP_POS_MSEC
Current position of the video in milliseconds.
1
cv2.CAP_PROP_POS_FRAMES
0-based index of the frame to be decoded/captured next.
3
cv2.CAP_PROP_FRAME_WIDTH
Width of the frames in the video stream.
4
cv2.CAP_PROP_FRAME_HEIGHT
Height of the frames in the video stream.
5
cv2.CAP_PROP_FPS
Frame rate of the video.
7
cv2.CAP_PROP_FRAME_COUNT
Number of frames of the video.
I have only mentioned the most commonly used properties with their Property ID and Enumerator. You can check cv2.VideoCaptureProperties for the remaining ones. Now we will try to get the width, height, frame rate, and the number of frames of the loaded video using the .get() function.
# Check if video accessed properly.
if (video_reader.isOpened()):

    # Get and display the width.
    width = video_reader.get(cv2.CAP_PROP_FRAME_WIDTH)
    print(f'Width of the video: {width}')

    # Get and display the height.
    height = video_reader.get(cv2.CAP_PROP_FRAME_HEIGHT)
    print(f'Height of the video: {height}')

    # Get and display the frame rate of the video.
    fps = video_reader.get(cv2.CAP_PROP_FPS)
    print(f'Frame rate of the video: {int(fps)}')

    # Get and display the number of frames of the video.
    frames_count = video_reader.get(cv2.CAP_PROP_FRAME_COUNT)
    print(f'Total number of frames of the video: {int(frames_count)}')

else:
    # Display the failure message.
    print("Failed to access the video!")
Width of the video: 1280.0
Height of the video: 720.0
Frame rate of the video: 29
Total number of frames of the video: 166
Now we will use the .set() function to set a new height and width of the loaded video. The function .set() returns False if the video property is not settable. This can happen when the resolution you are trying to set is not supported by your webcam or the video you are working on. The .set() function sets to the nearest resolution if that resolution is not settable like if I try to set the resolution to 500x500, it might fail to happen and the function set the resolution to something else, like 720x480, which is supported by my webcam.
# Specify the new width and height values.
new_width = 1920
new_height = 1080

# Check if video accessed properly.
if (video_reader.isOpened()):

    # Set width of the video if it is settable.
    if (video_reader.set(cv2.CAP_PROP_FRAME_WIDTH, new_width)):

        # Display the success message with new width.
        print("Now the width of the video is {new_width}")

    else:
        # Display the failure message.
        print("Failed to set the width!")

    # Set height of the video if it is settable.
    if (video_reader.set(cv2.CAP_PROP_FRAME_HEIGHT, new_height)):

        # Display the success message with new height.
        print("Now the height of the video is {new_height}")

    else:
        # Display the failure message.
        print("Failed to set the height!")

else:
    # Display the failure message.
    print("Failed to access the video!")
Failed to set the width!
Failed to set the height!
So we cannot set the width and height to 1920x1080 of the video we are working on. An easy solution to this type of issue can be to use the cv2.resize() function on each frame of the video but it is a little less efficient approach.
Now we will put all this in a loop and read and display all the frames sequentially in a window using the function cv2.imshow(), which will look like we are playing a video, but we will be just displaying frames one after the other. We will use the function cv2.waitKey(milliseconds) to wait for one millisecond before updating a frame with the next one.
We will use the functions .get() and .set() to keep restarting the video when every time we will reach the last frame until the key q is pressed, or the close X button on the opened window is pressed. And finally, in the end, we will release the loaded video using the function cv2.VideoCapture.release() and destroy all of the opened HighGUI windows by using cv2.destroyAllWindows().
# Initialize the VideoCapture object.
# video_reader = cv2.VideoCapture(0)
video_reader = cv2.VideoCapture('media/video.mp4')
# video_reader = cv2.VideoCapture('media/internet.gif')
# video_reader = cv2.VideoCapture('http://192.168.18.134:8080/video')

# Set width and height of the video if settable.
video_reader.set(3,1280)
video_reader.set(4,960)

# Create named window for resizing purposes.
cv2.namedWindow('Video', cv2.WINDOW_NORMAL)

# Initialize a variable to store the start time of the video.
start_time = time()

# Initialize a variable to store repeat video state.
repeat_video = True

# Initialize a variable to store the frame count.
frame_count = 0

# Iterate until the video is accessed successfully.
while video_reader.isOpened():

    # Read a frame.
    ret, frame = video_reader.read()

    # Check if frame is not read properly then break the loop
    if not ret:
        break

    # Increment the frame counter.
    frame_count+=1

    # Check if repeat video is enabled and the current frame is the last frame of the video.
    if repeat_video and frame_count == video_reader.get(cv2.CAP_PROP_FRAME_COUNT):

        # Set the current frame position to first frame to restart the video.
        video_reader.set(cv2.CAP_PROP_POS_FRAMES, 0)

        # Set the video frame counter to zero.
        frame_count = 0

        # Update the start time of the video.
        start_time = time()

    # Flip the frame horizontally for natural (selfie-view) visualization.
    frame = cv2.flip(frame, 1)

    # Get the height and width of frame.
    frame_height, frame_width, _  = frame.shape

    # Calaculate average frames per second.
    ##################################################################################################

    # Get the current time.
    curr_time = time()

    # Check if the difference between the start and current time > 0 to avoid division by zero.
    if (curr_time - start_time) > 0:

        # Calculate the number of frames per second.
        frames_per_second = frame_count // (curr_time - start_time)

        # Write the calculated number of frames per second on the frame.
        cv2.putText(frame, 'FPS: {}'.format(int(frames_per_second)), (10, frame_width//25),
                    cv2.FONT_HERSHEY_PLAIN, frame_width//300, (0, 255, 0), frame_width//200)

    ##################################################################################################

    # Display the frame.
    cv2.imshow('Video', frame)

    # Wait for 1ms. If a key is pressed, retreive the ASCII code of the key.
    k = cv2.waitKey(10) & 0xFF

    # Check if q key is pressed or the close 'X' button is pressed.
    if(k == ord('q')) or cv2.getWindowProperty('Video', cv2.WND_PROP_VISIBLE) < 1:

        # Break the loop.
        break

# Release the VideoCapture Object and close the windows.
video_reader.release()
cv2.destroyAllWindows()
You can increase the delay specified in cv2.waitKey(delay) to be higher than 1 ms to control the frames per second.
Join My Course Computer Vision For Building Cutting Edge Applications Course
The only course out there that goes beyond basic AI Applications and teaches you how to create next-level apps that utilize physics, deep learning, classical image processing, hand and body gestures. Don’t miss your chance to level up and take your career to new heights
You’ll Learn about:
Creating GUI interfaces for python AI scripts.
Creating .exe DL applications
Using a Physics library in Python & integrating it with AI
Advance Image Processing Skills
Advance Gesture Recognition with Mediapipe
Task Automation with AI & CV
Training an SVM machine Learning Model.
Creating & Cleaning an ML dataset from scratch.
Training DL models & how to use CNN’s & LSTMS.
Creating 10 Advance AI/CV Applications
& More
Whether you’re a seasoned AI professional or someone just looking to start out in AI, this is the course that will teach you, how to Architect & Build complex, real world and thrilling AI applications
In this tutorial, we learned what exactly videos are, how to read them from sources like IP camera, webcam, video files & gif, and display them frame by frame in a similar way an image is displayed. We also learned about the different properties of videos and how to get and set them in OpenCV.
These basic concepts we learned today are essential for many in-demand Computer Vision applications such as intelligent video analytics systems for intruder detection and much more.
You can reach out to me personally for a 1 on 1 consultation session in AI/computer vision regarding your project. Our talented team of vision engineers will help you every step of the way. Get on a call with me directlyhere.
Ready to seriously dive into State of the Art AI & Computer Vision? Then Sign up for these premium Courses by Bleed AI
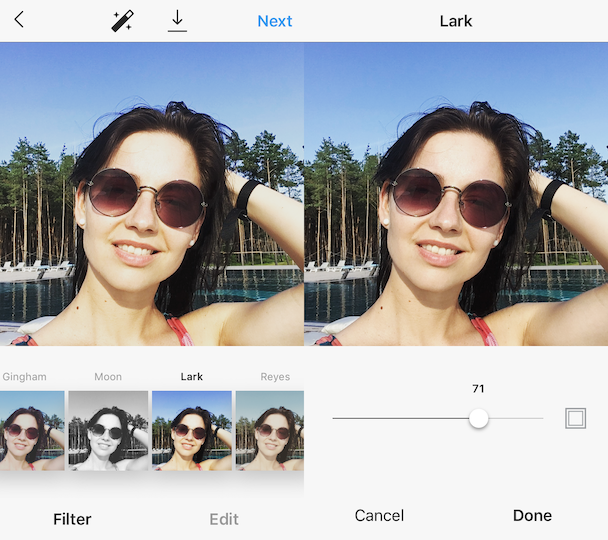
You must have tried or heard of the famous Instagram filters, if you haven’t then … well 🤔 please just let me know the year you are living in, along with the address of your cave xD in the comments section, I would love to visit you (I mean visit the past) someday. These filters are everywhere nowadays, every social media person is obsessed with these.
Being a vison/ml practitioner, you must have thought about creating one or at least have wondered how these filters completely change the vibe of an image. If yes, then here at Bleed AI we have published just the right series for you (Yes you heard right a complete series), in which you will learn to create some fascinating photo filters along with a user interface similar to the Instagram filter selection screen using OpenCV in python.
In Instagram (or any other photo filter application), we touch on the screen to select different filters from a list of filters previews to apply them to an image, similarly, if you want to select a filter (using a mouse) and apply it to an image in python, you might want to use OpenCV, specifically OpenCV’s Mouse events, and these filter applications normally also provide a slider to adjust the intensity of the selected filter, we can create something similar in OpenCV using a trackbar.
So in this tutorial, we will cover all the nitty-gritty details required to use Mouse Events (to select a filter) and TrackBars (to control the intensity of filters) in OpenCV, and to kill the dryness we will learn all these concepts by building some mini-applications, so trust me you won’t get bored.
This is the first tutorial in our 3 part Creating Instagram Filters series. All three posts are titled as:
Part 1: Working With Mouse & Trackbar Events in OpenCV (Current tutorial)
Part 2: Working With Lookup Tables & Applying Color Filters on Images & Videos
Part 3: Designing Advanced Image Filters in OpenCV
Outline
This tutorial can be split into the following parts:
Well, mouse events in OpenCV are the events that are triggered when a user interacts with an OpenCV image window using a mouse. OpenCV allows you to capture different types of mouse events like left-button down, left-button up, left-button double-click, etc, and then whenever these events occur, you can then execute some operation(s) accordingly, e.g. apply a certain filter.
Here are the most common mouse events that you can work with
Event ID
Enumerator
Event Indication
0
cv2.EVENT_MOUSEMOVE
Indicates that the mouse pointer has moved over the window.
1
cv2.EVENT_LBUTTONDOWN
Indicates that the left mouse button is pressed.
2
cv2.EVENT_RBUTTONDOWN
Indicates that the right mouse button is pressed.
3
cv2.EVENT_MBUTTONDOWN
Indicates that the middle mouse button is pressed.
4
cv2.EVENT_LBUTTONUP
Indicates that the left mouse button is released.
5
cv2.EVENT_RBUTTONUP
Indicates that the right mouse button is released.
6
cv2.EVENT_MBUTTONUP
Indicates that the middle mouse button is released.
7
cv2.EVENT_LBUTTONDBLCLK
Indicates that the left mouse button is double-clicked.
8
cv2.EVENT_RBUTTONDBLCLK
Indicates that the right mouse button is double-clicked.
9
cv2.EVENT_MBUTTONDBLCLK
Indicates that the middle mouse button is double-clicked.
I have only mentioned the most commonly triggered events with their Event IDs and Enumerators. You can check cv2.MouseEventTypes for the remainings.
Now for capturing these events, we will have to attach an event listener to an image window, so in simple words; we are just gonna be telling the OpenCV library to start reading the mouse input on an image window, this can be done easily by using the cv2.setMouseCallback() function.
winname: – The name of the window with which we’re gonna attach the mouse event listener.
onMouse: – The method (callback function) that is going to be called every time a mouse event is captured.
userdata: (optional) – A parameter passed to the callback function.
Now before we could use the above function two things should be done, first we must create a window beforehand since we will have to pass the window name to the cv2.setMouseCallback() function. For this we will use the cv2.namedWindow(winname) function.
# Create a named resizable window.
# This will create and open up a OpenCV image window.
# Minimize the window and run the next cells.
# Donot close this window.
cv2.namedWindow('Webcam Feed', cv2.WINDOW_NORMAL)
And the next thing we must do is to create a method (callback function) that is going to be called whenever a mouse event is captured. And this method by default will have a couple of arguments containing info related to the captured mouse event.
Creating a Paint Application utilizing Mouse Events
Now we will create a callback function drawShapes(), that will draw a circle or rectangle on an empty canvas(i.e. just an empty black image) at the location of the mouse cursor whenever the left or right mouse button is pressed respectively and clear the canvas whenever the middle mouse button is pressed.
def drawShapes(event, x, y, flags, userdata):
'''
This function will draw circle and rectangle on a canvas and clear it based
on different mouse events.
Args:
event: The mouse event that is captured.
x: The x-coordinate of the mouse pointer position on the window.
y: The y-coordinate of the mouse pointer position on the window.
flags: It is one of the MouseEventFlags constants.
userdata: The parameter passed from the `cv2.setMouseCallback()` function.
'''
# Access the canvas from outside of the current scope.
global canvas
# Check if the left mouse button is pressed.
if event == cv2.EVENT_LBUTTONDOWN:
# Draw a circle on the current location of the mouse pointer.
cv2.circle(img=canvas, center=(x, y), radius=50,
color=(113,182,255), thickness=-1)
# Check if the right mouse button is pressed.
elif event == cv2.EVENT_RBUTTONDOWN:
# Draw a rectangle on the current location of the mouse pointer.
cv2.rectangle(img=canvas, pt1=(x-50,y-50), pt2=(x+50,y+50),
color=(113,182,255), thickness=-1)
# Check if the middle mouse button is pressed.
elif event == cv2.EVENT_MBUTTONDOWN:
# Clear the canvas.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
Now it’s time to draw circles and rectangles on a webcam feed utilizing mouse events in real-time, as we have created a named window Webcam Feed and a callback function drawShapes() (to draw on a canvas), so we are all set to use the function cv2.setMouseCallback() to serve the purpose.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)
# Initialize a canvas to draw on.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
# Create a named resizable window.
# This line is added to re-create the window,
# in case you have closed the window created in the cell above.
cv2.namedWindow('Webcam Feed', cv2.WINDOW_NORMAL)
# Attach the mouse callback function to the window.
cv2.setMouseCallback('Webcam Feed', drawShapes)
# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():
# Read a frame.
ok, frame = camera_video.read()
# Check if frame is not read properly then
# continue to the next iteration to read the next frame.
if not ok:
continue
# Update the pixel values of the frame with the canvas's values at the indexes where canvas!=0
# i.e. where canvas is not black and something is drawn there.
# In short, this will copy the shapes from canvas to the frame.
frame[np.mean(canvas, axis=2)!=0] = canvas[np.mean(canvas, axis=2)!=0]
# Display the frame.
cv2.imshow('Webcam Feed', frame)
# Check if 'ESC' is pressed and break the loop.
if cv2.waitKey(20) & 0xFF == 27:
break
# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
Working as expected! but there’s a minor issue, we can only draw fixed size shapes so let’s try to overcome this limitation by creating another callback function drawResizableShapes() that will use the cv2.EVENT_MOUSEMOVE event, to measure the required size of a shape in real-time meaning the user will have to drag the mouse while pressing the right or left mouse button to draw shapes of different sizes on the canvas.
def drawResizableShapes(event, x, y, flags, userdata):
'''
This function will draw circle and rectangle on a canvas and clear it
on different mouse events.
Args:
event: The mouse event that is captured.
x: The x-coordinate of the mouse pointer position on the window.
y: The y-coordinate of the mouse pointer position on the window.
flags: It is one of the MouseEventFlags constants.
userdata: The parameter passed from the `cv2.setMouseCallback()` function.
'''
# Access the needed variables from outside of the current scope.
global start_x, start_y, canvas, draw_shape
# Check if the left mouse button is pressed.
if event == cv2.EVENT_LBUTTONDOWN:
# Enable the draw circle mode.
draw_shape = 'Circle'
# Set the start x and y to the current x and y values.
start_x = x
start_y = y
# Check if the left mouse button is pressed.
elif event == cv2.EVENT_RBUTTONDOWN:
# Enable the draw rectangle mode.
draw_shape = 'Rectangle'
# Set the start x and y to the current x and y values.
start_x = x
start_y = y
# Check if the mouse has moved on the window.
elif event == cv2.EVENT_MOUSEMOVE:
# Get the pointer x-coordinate distance between start and current point.
pointer_pos_diff_x = abs(start_x-x)
# Get the pointer y-coordinate distance between start and current point.
pointer_pos_diff_y = abs(start_y-y)
# Check if the draw circle mode is enabled.
if draw_shape == 'Circle':
# Draw a circle on the start x and y coordinates,
# of size depending upon the distance between start,
# and current x and y coordinates.
cv2.circle(img = canvas, center = (start_x, start_y),
radius = pointer_pos_diff_x + pointer_pos_diff_y,
color = (113,182,255), thickness = -1)
# Check if the draw rectangle mode is enabled.
elif draw_shape == 'Rectangle':
# Draw a rectangle on the start x and y coordinates,
# of size depending upon the distance between start,
# and current x and y coordinates.
cv2.rectangle(img=canvas, pt1=(start_x-pointer_pos_diff_x,
start_y-pointer_pos_diff_y),
pt2=(start_x+pointer_pos_diff_x, start_y+pointer_pos_diff_y),
color=(113,182,255), thickness=-1)
# Check if the left or right mouse button is released.
elif event == cv2.EVENT_LBUTTONUP or event == cv2.EVENT_RBUTTONUP:
# Disable the draw shapes mode.
draw_shape = None
# Check if the middle mouse button is pressed.
elif event == cv2.EVENT_MBUTTONDOWN:
# Clear the canvas.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
Now we are all set to overcome that same size limitation, we will utilize this drawResizableShapes() callback function created above, to draw circles and rectangles of various sizes on a webcam feed utilizing mouse events.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)
# Initialize a canvas to draw on.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
# Create a named resizable window.
cv2.namedWindow('Webcam Feed', cv2.WINDOW_NORMAL)
# Attach the mouse callback function to the window.
cv2.setMouseCallback('Webcam Feed', drawResizableShapes)
# Initialize variables to store start mouse pointer x and y location.
start_x = 0
start_y = 0
# Initialize a variable to store the draw shape mode.
draw_shape = None
# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():
# Read a frame.
ok, frame = camera_video.read()
# Check if frame is not read properly then
# continue to the next iteration to read the next frame.
if not ok:
continue
# Update the pixel values of the frame with the canvas's values at the indexes where canvas!=0
# i.e. where canvas is not black and something is drawn there.
# In short, this will copy the shapes from canvas to the frame.
frame[np.mean(canvas, axis=2)!=0] = canvas[np.mean(canvas, axis=2)!=0]
# Display the frame.
cv2.imshow('Webcam Feed', frame)
# Check if 'ESC' is pressed and break the loop.
if cv2.waitKey(20) & 0xFF == 27:
break
# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
Cool! right? feels like a mini paint application but still, something’s missing. How about adding a feature for users to paint (draw anything) with different colors to select from, and erase the drawings, on the webcam feed. All this just by utilizing mouse events in OpenCV, feels like a plan right? let’s create it. Again first we will have to create a callback function draw() that will carry all the heavy burden of drawing, erasing, and selecting paint color utilizing mouse events.
def draw(event, x, y, flags, userdata):
'''
This function will select paint color, draw and clear a canvas
based on different mouse events.
Args:
event: The mouse event that is captured.
x: The x-coordinate of the mouse pointer position on the window.
y: The y-coordinate of the mouse pointer position on the window.
flags: It is one of the MouseEventFlags constants.
userdata: The parameter passed from the `cv2.setMouseCallback()` function.
'''
# Access the needed variables from outside of the current scope.
global prev_x, prev_y, canvas, mode, color
# Check if the left mouse button is double-clicked.
if event == cv2.EVENT_LBUTTONDBLCLK:
# Check if the mouse pointer y-coordinate is less than equal to a certain threshold.
if y <= 10 + rect_height:
# Check if the mouse pointer x-coordinate is over the orange color rectangle.
if x>(frame_width//1.665-rect_width//2) and \
x<(frame_width//1.665-rect_width//2)+rect_width:
# Update the color variable value to orange.
color = 113, 182, 255
# Check if the mouse pointer x-coordinate is over the pink color rectangle.
elif x>(int(frame_width//2)-rect_width//2) and \
x<(int(frame_width//2)-rect_width//2)+rect_width:
# Update the color variable value to pink.
color = 203, 192, 255
# Check if the mouse pointer x-coordinate is over the yellow color rectangle.
elif x>(int(frame_width//2.5)-rect_width//2) and \
x<(int(frame_width//2.5)-rect_width//2)+rect_width:
# Update the color variable value to yellow.
color = 0, 255, 255
# Check if the left mouse button is pressed.
elif event == cv2.EVENT_LBUTTONDOWN:
# Enable the paint mode.
mode = 'Paint'
# Check if the right mouse button is pressed.
elif event == cv2.EVENT_RBUTTONDOWN:
# Enable the paint mode.
mode = 'Erase'
# Check if the left or right mouse button is released.
elif event == cv2.EVENT_LBUTTONUP or event == cv2.EVENT_RBUTTONUP:
# Disable the active mode.
mode = None
# Reset by updating the previous x and y values to None.
prev_x = None
prev_y = None
# Check if the mouse has moved on the window.
elif event == cv2.EVENT_MOUSEMOVE:
# Check if a mode is enabled and the previous x and y donot have valid values.
if mode and (not (prev_x and prev_y)):
# Set the previous x and y to the current x and y values.
prev_x = x
prev_y = y
# Check if the paint mode is enabled.
if mode == 'Paint':
# Draw a line from previous x and y to the current x and y.
cv2.line(img=canvas, pt1=(x,y), pt2=(prev_x,prev_y), color=color, thickness=10)
# Check if the erase mode is enabled.
elif mode == 'Erase':
# Draw a black line from previous x and y to the current x and y.
# This will erase the paint between previous x and y and the current x and y.
cv2.line(img=canvas, pt1=(x,y), pt2=(prev_x,prev_y), color=(0,0,0), thickness=20)
# Update the previous x and y to the current x and y values.
prev_x = x
prev_y = y
# Check if the middle mouse button is pressed.
elif event == cv2.EVENT_MBUTTONDOWN:
# Clear the canvas.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
Now that we have created a drawing callback function draw(), it's time to use it to create that paint application we had in mind, the application will draw, erase on a webcam feed with different colors utilizing mouse events in real-time.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)
# Initialize a canvas to draw on.
canvas = np.zeros(shape=(int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT)),
int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH)), 3),
dtype=np.uint8)
# Create a named resizable window.
cv2.namedWindow('Webcam Feed', cv2.WINDOW_NORMAL)
# Attach the mouse callback function to the window.
cv2.setMouseCallback('Webcam Feed', draw)
# Initialize variables to store previous mouse pointer x and y location.
prev_x = None
prev_y = None
# Initialize a variable to store the active mode.
mode = None
# Initialize a variable to store the color value.
color = 203, 192, 255
# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():
# Read a frame.
ok, frame = camera_video.read()
# Check if frame is not read properly then
# continue to the next iteration to read the next frame.
if not ok:
continue
# Get the height and width of the frame of the webcam video.
frame_height, frame_width, _ = frame.shape
# Get the colors rectangles previews height and width.
rect_height, rect_width = int(frame_height/10), int(frame_width/10)
# Update the pixel values of the frame with the canvas's values at the indexes where canvas!=0
# i.e. where canvas is not black and something is drawn there.
# In short, this will copy the drawings from canvas to the frame.
frame[np.mean(canvas, axis=2)!=0] = canvas[np.mean(canvas, axis=2)!=0]
# Overlay the colors previews rectangles over the frame.
###################################################################################################################
# Overlay the orange color preview on the frame.
cv2.rectangle(img=frame, pt1=(int((frame_width//1.665)-rect_width//2), 10),
pt2=(int((frame_width//1.665)+rect_width//2), 10+rect_height),
color=(113, 182, 255), thickness=-1)
# Draw an outline around the orange color preview.
cv2.rectangle(img=frame, pt1=(int((frame_width//1.665)-rect_width//2), 10),
pt2=(int((frame_width//1.665)+rect_width//2), 10+rect_height),
color=(255, 255, 255), thickness=2)
# Overlay the pink color preview on the frame.
cv2.rectangle(img=frame, pt1=(int((frame_width//2)-rect_width//2), 10),
pt2=(int((frame_width//2)+rect_width//2), 10+rect_height),
color=(203, 192, 255), thickness=-1)
# Draw an outline around the pink color preview.
cv2.rectangle(img=frame, pt1=(int((frame_width//2)-rect_width//2), 10),
pt2=(int((frame_width//2)+rect_width//2), 10+rect_height),
color=(255, 255, 255), thickness=2)
# Overlay the yellow color preview on the frame.
cv2.rectangle(img=frame, pt1=(int((frame_width//2.5)-rect_width//2), 10),
pt2=(int((frame_width//2.5)+rect_width//2), 10+rect_height),
color=(0, 255, 255), thickness=-1)
# Draw an outline around the yellow color preview.
cv2.rectangle(img=frame, pt1=(int((frame_width//2.5)-rect_width//2), 10),
pt2=(int((frame_width//2.5)+rect_width//2), 10+rect_height),
color=(255, 255, 255), thickness=2)
###################################################################################################################
# Display the frame.
cv2.imshow('Webcam Feed', frame)
# Check if 'ESC' is pressed and break the loop.
if cv2.waitKey(20) & 0xFF == 27:
break
# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
Awesome! Everything went according to the plan, the application is working fine. But there's a minor issue that we have limited options to choose the paint color from. We can add more colors previews on the frame and add code to select those colors using mouse events but that will take forever, I wish there was a simpler way.
Working with TrackBars in OpenCV
Well, there's a way to get around this i.e., using TrackBars, as I mentioned at the beginning of the tutorial, these are like sliders with a minimum and a maximum value and allow users to slide across and select a value. These are extremely beneficial in adjusting the parameters of things in code in real-time instead of manually changing them and running the code again and again. For our case, these can be very handy to choose filters intensity and paint color (RGB) value in real-time.
OpenCV allows creating trackbars by using the cv2.createTrackbar() function. The procedure is pretty similar to that of cv2.setMouseCallback() function, first we will have to create a namedwindow, then create a method (i.e. called onChange in the slider) and finally attach the trackbar to that window using the function cv2.createTrackbar().
Trackbar_Name: It is the name of the trackbar you wish to get the value of.
winname: It is the name of the window that the trackbar is attached to.
Now let's create a simple python script that will utilize trackbars to move a circle around in a webcam feed window and adjust its radius in real-time.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)
# Create a named resizable window.
cv2.namedWindow('Webcam Feed', cv2.WINDOW_NORMAL)
# Get the height and width of the frame of the webcam video.
frame_height = int(camera_video.get(cv2.CAP_PROP_FRAME_HEIGHT))
frame_width = int(camera_video.get(cv2.CAP_PROP_FRAME_WIDTH))
# Create the onChange function for the trackbar since its mandatory.
def nothing(x):
pass
# Create trackbar named Radius with the range [0-100].
cv2.createTrackbar('Radius: ', 'Webcam Feed', 50, 100, nothing)
# Create trackbar named x with the range [0-frame_width].
cv2.createTrackbar('x: ', 'Webcam Feed', 50, frame_width, nothing)
# Create trackbar named y with the range [0-frame_height].
cv2.createTrackbar('y: ', 'Webcam Feed', 50, frame_height, nothing)
# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():
# Read a frame.
ok, frame = camera_video.read()
# Check if frame is not read properly then continue to the next iteration to read the next frame.
if not ok:
continue
# Get the value of the radius of the circle (ball).
radius = cv2.getTrackbarPos('Radius: ', 'Webcam Feed')
# Get the x-coordinate value of the center of the circle (ball).
x = cv2.getTrackbarPos('x: ', 'Webcam Feed')
# Get the y-coordinate value of the center of the circle (ball).
y = cv2.getTrackbarPos('y: ', 'Webcam Feed')
# Draw the circle on the frame.
cv2.circle(img=frame, center=(x, y),
radius=radius, color=(113,182,255), thickness=-1)
# Display the frame.
cv2.imshow('Webcam Feed', frame)
# Check if 'ESC' key is pressed and break the loop.
if cv2.waitKey(20) & 0x FF == 27:
break
# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
I don't know why, but this kind of reminds me of my childhood when I used to spend hours playing that famous Bouncing Ball Game on my father's Nokia phone 😂. But the ball (circle) we moved using trackbars wasn't bouncing, in fact there was no game mechanics, but hey you can actually change that if you want by adding actual physical properties ( like mass, force, acceleration, and everything ) to this ball (circle) using Pymunk library.
Create 3 trackbars to control the RGB paint color in the paint application above and draw a resizable Ellipse on webcam feed utilizing mouse events and share the results with me in the comments section.
Join My Course Computer Vision For Building Cutting Edge Applications Course
The only course out there that goes beyond basic AI Applications and teaches you how to create next-level apps that utilize physics, deep learning, classical image processing, hand and body gestures. Don’t miss your chance to level up and take your career to new heights
You’ll Learn about:
Creating GUI interfaces for python AI scripts.
Creating .exe DL applications
Using a Physics library in Python & integrating it with AI
Advance Image Processing Skills
Advance Gesture Recognition with Mediapipe
Task Automation with AI & CV
Training an SVM machine Learning Model.
Creating & Cleaning an ML dataset from scratch.
Training DL models & how to use CNN's & LSTMS.
Creating 10 Advance AI/CV Applications
& More
Whether you're a seasoned AI professional or someone just looking to start out in AI, this is the course that will teach you, how to Architect & Build complex, real world and thrilling AI applications
In today’s tutorial, we went over almost all minor details regarding Mouse Events and TrackBars and used them to make a few fun applications.
First, we used mouse events to draw fixed size shapes, then we realized this size limitation and got around it by drawing shapes of different sizes. After that, we created a mini paint application capable of drawing anything, it had 3 different colors to select from and also had an option for erasing the drawings. And all of this ran on the live webcam feed. We then also learned about TrackBars in OpenCV and why they are useful and then we utilized them to move a resizable circle around on a webcam feed.
Also, don't forget that our ultimate goal for creating all these mini-applications was to get you familiar with Mouse Events and TrackBars. As we will need these to select a filter and change the applied filter intensity in real-time in the next post of this series, so buckle up, as things are about to get more interesting in the next week's post.
Let me know in the comments If you have any questions!
Hire Us
Let our team of expert engineers and managers build your next big project using Bleeding Edge AI Tools & Technologies
In the previous tutorial of this series, we learned how the mouse events and trackbars work in OpenCV, we went into all the details needed for you to get comfortable with using these. Now in this tutorial, we will learn to create a user interface similar to the Instagram filter selection screen using mouse events & trackbars in OpenCV.
But first, we will learn what LookUp Tables are, why are they preferred along with their use cases in real-life, and then utilize these LookUp Tables to create some spectacular photo effects called Color Filters a.k.a. Tone Effects.
This Tutorial is built on top of the previous one so if you haven’t read the previous post and don’t know how to use mouse events and trackbars in OpenCV, then you can read that post here. As we are gonna utilize trackbars to control the intensities of the filters and mouse events to select a Color filter to apply.
This is the second tutorial in our 3 part Creating Instagram Filters series (in which we will learn to create some interesting and famous Instagram filters-like effects). All three posts are titled as:
import cv2
import numpy as np
import matplotlib.pyplot as plt
Introduction to LookUp Tables
LookUp Tables (also known as LUTs) in OpenCV are arrays containing a mapping of input values to output values that allow replacing computationally expensive operations with a simpler array indexing operation at run-time.* Don’t worry in case the definition felt like mumbo-jumbo to you, I am gonna break down this to you in a very digestible and intuitive manner. Check the image below containing a LookUp Table of Square operation.
So it’s just a mapping of a bunch of input values to their corresponding outputs i.e., normally outcomes of a certain operation (like square in the image above) on the input values. These are structured in an array containing the output mapping values at the indexes equal to the input values. Meaning the output for the input value 2 will be at the index 2 in the array, and i.e., 4 in the image above. Now that we know what exactly these LookUp Tables are, so let’s move to create one for the square operation.
# Initialize a list to store the LookUpTable mapping.
square_table = []

# Iterate over 100 times.
# We are creating mapping only for input values [0-99].
for i in range(100):

    # Take Square of the i and append it into the list.
    square_table.append(pow(i, 2))

# Convert the list into an array.
square_table = np.array(square_table)

# Display first ten elements of the lookUp table.
print(f'First 10 mappings: {square_table[:10]}')
First 10 mappings: [ 0 1 4 9 16 25 36 49 64 81]
This is how a LookUp Table is created, yes it’s that simple. But you may be thinking how and for what are they used for? Well as mentioned in the definition, these are used to replace computationally expensive operations (in our example, Square) with a simpler array indexing operation at run-time.
So in simple words instead of calculating the results at run-time, these allow to transform input values into their corresponding outputs by looking up in the mapping table by doing something like this:
# Set the input value to get its square from the LookUp Table.
input_value = 10

# Display the output value returned from the LookUp Table.
print(f'Square of {input_value} is: {square_table[input_value]}')
Square of 10 is: 100
This eliminates the need of performing a computationally expensive operation at run-time as long as the input values have a limited range which is always true for images as they have pixels intensities [0-255].
Almost all the image processing operations can be performed much more efficiently using these LookUp Tables like increasing/decreasing image brightness, saturation, contrast, even changing specific colors in images like the black and white color shift done in the image below.
Stunning! right? let’s try to perform this color shift on a few sample images. First, we will construct a LookUp Table mapping all the pixel values greater than 220 (white) to 0 (black) and then transform an image according to the lookup table using the cv2.LUT() function.
src: – It is the input array (image) of 8-bit elements.
lut: – It is the look-up table of 256 elements.
Returns:
dst: – It is the output array of the same size and number of channels as src, and the same depth as lut.
Note:In the case of a multi-channel input array (src), the table (lut) should either have a single channel (in this case the same table is used for all channels) or the same number of channels as in the input array (src).
# Read a sample image.
image = cv2.imread('media/sample.jpg')

# Initialize a list to store the lookuptable mapping.
white_to_black_table = []

# Iterate over 256 times.
# As images have pixels intensities [0-255].
for i in range(256):

    # Check if i is greater than 220.
    if i > 220:

        # Append 0 into the list.
        # This will convert pixels > 220 to 0.
        white_to_black_table.append(0)

    # Otherwise.
    else:

        # Append i into the list.
        # The pixels <= 220 will remain the same.
        white_to_black_table.append(i)

# Transform the image according to the lookup table.
output_image = cv2.LUT(image, np.array(white_to_black_table).astype("uint8"))

# Display the original sample image and the resultant image.
plt.figure(figsize=[15,15])
plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Sample Image");plt.axis('off');
plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');
As you can see it worked as expected. Now let’s construct another LookUp Table mapping all the pixel values less than 50 (black) to 255 (white) and then transform another sample image to switch the black color in the image with white.
# Read another sample image.
image = cv2.imread('media/wall.jpg')

# Initialize a list to store the lookuptable mapping.
black_to_white_table = []

# Iterate over 256 times.
for i in range(256):

    # Check if i is less than 50.
    if i < 50:

        # Append 255 into the list.
        black_to_white_table.append(255)

    # Otherwise.
    else:

        # Append i into the list.
        black_to_white_table.append(i)

# Transform the image according to the lookup table.
output_image = cv2.LUT(image, np.array(black_to_white_table).astype("uint8"))

# Display the original sample image and the resultant image.
plt.figure(figsize=[15,15])
plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Sample Image");plt.axis('off');
plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');
The Black to white shift is also working perfectly fine. You can perform a similar shift with any color you want and this technique can be really helpful in efficiently changing green background screens from high-resolution videos and creating some interesting effects.
But we still don’t have an idea how much computational power and time these LookUp Tables save and are they worth trying? Well, this completely depends upon your use case, the number of images you want to transform, the resolution of the images you are working on, etc.
How about we perform a black to white shift on a few images with and without LookUp Tables and note the execution time to get an idea of the time difference? You can change the number of images and their resolution according to your use case.
# Set the number of images and their resolution.
num_of_images = 100
image_resolution = (960, 1280)
First, let’s do it without using LookUp Tables.
%%time
# Use magic command to measure execution time.

# Iterate over the number of times equal to the number of images.
for i in range(num_of_images):

    # Create a dummy image with each pixel value equal to 0.
    image = np.zeros(shape=image_resolution, dtype=np.uint8)

    # Convert pixels < 50 to 255.
    image[image<50] = 255
Wall time: 194 ms
We have the execution time without using LookUp Tables, now let’s check the difference by performing the same operation utilizing LookUp Tables. First we will create the look up Table, this only has to be done once.
# Initialize a list to store the lookuptable mapping.
table = []

# Iterate over 256 times.
for i in range(256):

     # Check if i is less than 50.
    if i < 50:

        # Append 255 into the list.
        table.append(255)

    # Otherwise.
    else:

        # Append i into the list.
        table.append(i)
Now we’ll use the look up table created above in action
%%time
# Use magic command to measure execution time.

# Iterate over the number of times equal to the number of images.
for i in range(num_of_images):

    # Create a dummy image with each pixel value equal to 0.
    image = np.zeros(shape=image_resolution, dtype=np.uint8)

    # Transform the image according to the lookup table.
    cv2.LUT(image, np.array(table).astype("uint8"))
Wall time: 81.2 ms
So the time taken in the second approach (LookUp Tables) is significantly lesser while the results are the same.
Applying Color Filters on Images/Videos
Finally comes the fun part, Color Filters that give interesting lighting effects to images, simply by modifying pixel values of different color channels (R,G,B) of images and we will create some of these effects utilizing LookUp tables.
We will first construct a lookup table, containing the mapping that we will need to apply different color filters.
# Initialize a list to store the lookuptable for the color filter.
color_table = []

# Iterate over 128 times from 128-255.
for i in range(128, 256):

    # Extend the table list and add the i two times in the list.
    # We want to increase pixel intensities that's why we are adding only values > 127.
    # We are adding same value two times because we need total 256 elements in the list.
    color_table.extend([i, i])
# We just added each element 2 times.
print(color_table[:10], "Length of table: " + str(len(color_table)))
Now we will create a function applyColorFilter() that will utilize the lookup table we created above, to increase pixel intensities of specified channels of images and videos and will display the resultant image along with the original image or return the resultant image depending upon the passed arguments.
def applyColorFilter(image, channels_indexes, display=True):
    '''
    This function will apply different interesting color lighting effects on an image.
    Args:
        image:            The image on which the color filter is to be applied.
        channels_indexes: A list of channels indexes that are required to be transformed.
        display:          A boolean value that is if set to true the function displays the original image,
                          and the output image with the color filter applied and returns nothing.
    Returns:
        output_image: The transformed resultant image on which the color filter is applied.
    '''

    # Access the lookuptable containing the mapping we need.
    global color_table

    # Create a copy of the image.
    output_image = image.copy()

    # Iterate over the indexes of the channels to modify.
    for channel_index in channels_indexes:

        # Transform the channel of the image according to the lookup table.
        output_image[:,:,channel_index] = cv2.LUT(output_image[:,:,channel_index],
                                                  np.array(color_table).astype("uint8"))

    # Check if the original input image and the resultant image are specified to be displayed.
    if display:

        # Display the original input image and the resultant image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Sample Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise
    else:

        # Return the resultant image.
        return output_image
Now we will utilize the function applyColorFilter() to apply different color effects on a few sample images and display the results.
# Read a sample image and apply color filter on it.
image = cv2.imread('media/sample1.jpg')
applyColorFilter(image, channels_indexes=[0])
# Read another sample image and apply color filter on it.
image = cv2.imread('media/sample2.jpg')
applyColorFilter(image, channels_indexes=[1])
# Read another sample image and apply color filter on it.
image = cv2.imread('media/sample3.jpg')
applyColorFilter(image, channels_indexes=[2])
# Read another sample image and apply color filter on it.
image = cv2.imread('media/sample4.jpg')
applyColorFilter(image, channels_indexes=[0, 1])
# Read another sample image and apply color filter on it.
image = cv2.imread('media/sample5.jpg')
applyColorFilter(image, channels_indexes=[0, 2])
Cool! right? the results are astonishing but some of them are feeling a bit too much. So how about we will create another function changeIntensity() to control the intensity of these filters, again by utilizing LookUpTables. The function will simply increase or decrease the pixel intensities of the same color channels that were modified by the applyColorFilter() function and will display the results or return the resultant image depending upon the passed arguments.
For modifying the pixel intensities we will use the Gamma Correction technique, also known as the Power Law Transform. Its a nonlinear operation normally used to correct the brightness of an image using the following equation:
O=(I255)γ×255
Here γ<1 will increase the pixel intensities while γ>1 will decrease the pixel intensities and the filter effect. To perform the process, we will first construct a lookup table using the equation above.
# Initialize a variable to store previous gamma value.
prev_gamma = 1.0

# Initialize a list to store the lookuptable for the change intensity operation.
intensity_table = []

# Iterate over 256 times.
for i in range(256):

    # Calculate the mapping output value for the i input value,
    # and clip (limit) the values between 0 and 255.
    # Also append it into the look-up table list.
    intensity_table.append(np.clip(a=pow(i/255.0, prev_gamma)*255.0, a_min=0, a_max=255))
And then we will create the changeIntensity() function, which will use the table we have constructed and will re-construct the table every time the gamma value changes.
def changeIntensity(image, scale_factor, channels_indexes, display=True):
    '''
    This function will change intensity of the color filters.
    Args:
        image:            The image on which the color filter intensity is required to be changed.
        scale_factor:     A number that will be used to calculate the required gamma value.
        channels_indexes: A list of indexes of the channels on which the color filter was applied.
        display:          A boolean value that is if set to true the function displays the original image,
                          and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the color filter intensity changed.
    '''

    # Access the previous gamma value and the table contructed
    # with the previous gamma value.
    global prev_gamma, intensity_table

    # Create a copy of the input image.
    output_image = image.copy()

    # Calculate the gamma value from the passed scale factor.
    gamma = 1.0/scale_factor

    # Check if the previous gamma value is not equal to the current gamma value.
    if gamma != prev_gamma:

        # Update the intensity lookuptable to an empty list.
        # We will have to re-construct the table for the new gamma value.
        intensity_table = []

        # Iterate over 256 times.
        for i in range(256):

            # Calculate the mapping output value for the i input value
            # And clip (limit) the values between 0 and 255.
            # Also append it into the look-up table list.
            intensity_table.append(np.clip(a=pow(i/255.0, gamma)*255.0, a_min=0, a_max=255))

        # Update the previous gamma value.
        prev_gamma = gamma

    # Iterate over the indexes of the channels.
    for channel_index in channels_indexes:

        # Change intensity of the channel of the image according to the lookup table.
        output_image[:,:,channel_index] = cv2.LUT(output_image[:,:,channel_index],
                                                  np.array(intensity_table).astype("uint8"))

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Color Filter");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Color Filter with Modified Intensity")
        plt.axis('off')

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now let’s check how the changeIntensity() function works on a few sample images.
# Read a sample image and apply color filter on it with intensity 0.6.
image = cv2.imread('media/sample5.jpg')
image = applyColorFilter(image, channels_indexes=[1, 2], display=False)
changeIntensity(image, scale_factor=0.6, channels_indexes=[1, 2])
# Read another sample image and apply color filter on it with intensity 3.
image = cv2.imread('media/sample2.jpg')
image = applyColorFilter(image, channels_indexes=[2], display=False)
changeIntensity(image, scale_factor=3, channels_indexes=[2])
Apply Color Filters On Real-Time Web-cam Feed
The results on the images are exceptional, now let’s check how these filters will look on a real-time webcam feed. But first, we will create a mouse event callback function selectFilter(), that will allow us to select the filter to apply by clicking on the filter preview on the top of the frame in real-time.
def selectFilter(event, x, y, flags, userdata):
    '''
    This function will update the current filter applied on the frame based on different mouse events.
    Args:
        event:    The mouse event that is captured.
        x:        The x-coordinate of the mouse pointer position on the window.
        y:        The y-coordinate of the mouse pointer position on the window.
        flags:    It is one of the MouseEventFlags constants.
        userdata: The parameter passed from the `cv2.setMouseCallback()` function.
    '''

    # Access the filter applied and the channels indexes variable.
    global filter_applied, channels_indexes

    # Check if the left mouse button is pressed.
    if event == cv2.EVENT_LBUTTONDOWN:

        # Check if the mouse pointer y-coordinate is less than equal to a certain threshold.
        if y <= 10+preview_height:

            # Check if the mouse pointer x-coordinate is over the Blue filter ROI.
            if x > (int(frame_width//1.25)-preview_width//2) and \
            x < (int(frame_width//1.25)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Blue.
                filter_applied = 'Blue'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Blue filter.
                channels_indexes = [0]

            # Check if the mouse pointer x-coordinate is over the Green filter ROI.
            elif x>(int(frame_width//1.427)-preview_width//2) and \
            x<(int(frame_width//1.427)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Green.
                filter_applied = 'Green'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Green filter.
                channels_indexes = [1]

            # Check if the mouse pointer x-coordinate is over the Red filter ROI.
            elif x>(frame_width//1.665-preview_width//2) and \
            x<(frame_width//1.665-preview_width//2)+preview_width:

                # Update the filter applied variable value to Red.
                filter_applied = 'Red'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Red filter.
                channels_indexes = [2]

            # Check if the mouse pointer x-coordinate is over the Normal frame ROI.
            elif x>(int(frame_width//2)-preview_width//2) and \
            x<(int(frame_width//2)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Normal.
                filter_applied = 'Normal'

                # Update the channels indexes list to empty list.
                # As no channels are modified in the Normal filter.
                channels_indexes = []

            # Check if the mouse pointer x-coordinate is over the Cyan filter ROI.
            elif x>(int(frame_width//2.5)-preview_width//2) and \
            x<(int(frame_width//2.5)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Cyan Filter.
                filter_applied = 'Cyan'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Cyan filter.
                channels_indexes = [0, 1]

            # Check if the mouse pointer x-coordinate is over the Purple filter ROI.
            elif x>(int(frame_width//3.33)-preview_width//2) and \
            x<(int(frame_width//3.33)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Purple.
                filter_applied = 'Purple'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Purple filter.
                channels_indexes = [0, 2]

            # Check if the mouse pointer x-coordinate is over the Yellow filter ROI.
            elif x>(int(frame_width//4.99)-preview_width//2) and \
            x<(int(frame_width//4.99)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Yellow.
                filter_applied = 'Yellow'

                # Update the channels indexes list to store the
                # indexes of the channels to modify for the Yellow filter.
                channels_indexes = [1, 2]
Now without further ado, let’s test the filters on a real-time webcam feed, we will be switching between the filters by utilizing the selectFilter() function created above and will use a trackbar to change the intensity of the filter applied in real-time.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(0)
camera_video.set(3,1280)
camera_video.set(4,960)

# Create a named resizable window.
cv2.namedWindow('Color Filters', cv2.WINDOW_NORMAL)

# Create the function for the trackbar since its mandatory.
def nothing(x):
    pass

# Create trackbar named Intensity with the range [0-100].
cv2.createTrackbar('Intensity', 'Color Filters', 50, 100, nothing)

# Attach the mouse callback function to the window.
cv2.setMouseCallback('Color Filters', selectFilter)

# Initialize a variable to store the current applied filter.
filter_applied = 'Normal'

# Initialize a list to store the indexes of the channels
# that were modified to apply the current filter.
# This list will be required to change intensity of the applied filter.
channels_indexes = []

# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():

    # Read a frame.
    ok, frame = camera_video.read()

    # Check if frame is not read properly then
    # continue to the next iteration to read the next frame.
    if not ok:
        continue

    # Flip the frame horizontally for natural (selfie-view) visualization.
    frame = cv2.flip(frame, 1)

    # Get the height and width of the frame of the webcam video.
    frame_height, frame_width, _ = frame.shape

    # Initialize a dictionary and store the copies of the frame with the
    # filters applied by transforming some different channels combinations.
    filters = {'Normal': frame.copy(),
               'Blue': applyColorFilter(frame, channels_indexes=[0], display=False),
               'Green': applyColorFilter(frame, channels_indexes=[1], display=False),
               'Red': applyColorFilter(frame, channels_indexes=[2], display=False),
               'Cyan': applyColorFilter(frame, channels_indexes=[0, 1], display=False),
               'Purple': applyColorFilter(frame, channels_indexes=[0, 2], display=False),
               'Yellow': applyColorFilter(frame, channels_indexes=[1, 2], display=False)}

    # Initialize a list to store the previews of the filters.
    filters_previews = []

    # Iterate over the filters dictionary.
    for filter_name, filter_applied_frame in filters.items():

        # Check if the filter we are iterating upon, is applied.
        if filter_applied == filter_name:

            # Set color to green.
            # This will be the border color of the filter preview.
            # And will be green for the filter applied and white for the other filters.
            color = (0,255,0)

        # Otherwise.
        else:

            # Set color to white.
            color = (255,255,255)

        # Make a border around the filter we are iterating upon.
        filter_preview = cv2.copyMakeBorder(src=filter_applied_frame, top=100,
                                            bottom=100, left=10, right=10,
                                            borderType=cv2.BORDER_CONSTANT, value=color)

        # Resize the filter applied frame to the 1/10th of its current width
        # while keeping the aspect ratio constant.
        filter_preview = cv2.resize(filter_preview,
                                    (frame_width//10,
                                     int(((frame_width//10)/frame_width)*frame_height)))

        # Append the filter preview into the list.
        filters_previews.append(filter_preview)

    # Update the frame with the currently applied Filter.
    frame = filters[filter_applied]

    # Get the value of the filter intensity from the trackbar.
    filter_intensity = cv2.getTrackbarPos('Intensity', 'Color Filters')/100 + 0.5

    # Check if the length of channels indexes list is > 0.
    if len(channels_indexes) > 0:

        # Change the intensity of the applied filter.
        frame = changeIntensity(frame, filter_intensity,
                                channels_indexes,  display=False)

    # Get the new height and width of the previews.
    preview_height, preview_width, _ = filters_previews[0].shape

    # Overlay the resized preview filter images over the frame by updating
    # its pixel values in the region of interest.
    #######################################################################################

    # Overlay the Blue Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.25)-preview_width//2):\
          (int(frame_width//1.25)-preview_width//2)+preview_width] = filters_previews[1]

    # Overlay the Green Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.427)-preview_width//2):\
          (int(frame_width//1.427)-preview_width//2)+preview_width] = filters_previews[2]

    # Overlay the Red Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.665)-preview_width//2):\
          (int(frame_width//1.665)-preview_width//2)+preview_width] = filters_previews[3]

    # Overlay the normal frame (no filter) preview on the frame.
    frame[10: 10+preview_height,
          (frame_width//2-preview_width//2):\
          (frame_width//2-preview_width//2)+preview_width] = filters_previews[0]

    # Overlay the Cyan Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//2.5)-preview_width//2):\
          (int(frame_width//2.5)-preview_width//2)+preview_width] = filters_previews[4]

    # Overlay the Purple Filter preview on the frame.
    frame[10: 10+preview_height,
      (int(frame_width//3.33)-preview_width//2):\
          (int(frame_width//3.33)-preview_width//2)+preview_width] = filters_previews[5]

    # Overlay the Yellow Filter preview on the frame.
    frame[10: 10+preview_height,
      (int(frame_width//4.99)-preview_width//2):\
          (int(frame_width//4.99)-preview_width//2)+preview_width] = filters_previews[6]

    #######################################################################################

    # Display the frame.
    cv2.imshow('Color Filters', frame)

    # Wait for 1ms. If a key is pressed, retreive the ASCII code of the key.
    k = cv2.waitKey(1) & 0xFF

    # Check if 'ESC' is pressed and break the loop.
    if(k == 27):
        break

# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
As expected, the results are fascinating on videos as well.
Assignment (Optional)
Apply a different color filter on the foreground and a different color filter on the background, and share the results with me in the comments section. You can use MediaPipe’s Selfie Segmentation solution to segment yourself in order to differentiate the foreground and the background.
Join My Course Computer Vision For Building Cutting Edge Applications Course
The only course out there that goes beyond basic AI Applications and teaches you how to create next-level apps that utilize physics, deep learning, classical image processing, hand and body gestures. Don’t miss your chance to level up and take your career to new heights
You’ll Learn about:
Creating GUI interfaces for python AI scripts.
Creating .exe DL applications
Using a Physics library in Python & integrating it with AI
Advance Image Processing Skills
Advance Gesture Recognition with Mediapipe
Task Automation with AI & CV
Training an SVM machine Learning Model.
Creating & Cleaning an ML dataset from scratch.
Training DL models & how to use CNN’s & LSTMS.
Creating 10 Advance AI/CV Applications
& More
Whether you’re a seasoned AI professional or someone just looking to start out in AI, this is the course that will teach you, how to Architect & Build complex, real world and thrilling AI applications
Today, in this tutorial, we went over every bit of detail about the LookUp Tables, we learned what these LookUp Tables are, why they are useful and the use cases in which you should prefer them. Then we used these LookUp Tables to create different lighting effects (called Color Filters) on images and videos.
We utilized the concepts we learned about the Mouse Events and TrackBars in the previous tutorial of the series to switch between filters from the available options and change the applied filter intensity in real-time. Now in the next and final tutorial of the series, we will create some famous Instagram filters, so stick around for that.
And keep in mind that our intention was to teach you these crucial image processing concepts so that’s why we went for building the whole application using OpenCV (to keep the tutorial simple) but I do not think we have done justice with the user interface part, there’s room for a ton of improvements.
There are a lot of GUI libraries like PyQt, Pygame, and Kivi (to name a few) that you can use in order to make the UI more appealing for this application.
In the previous tutorial of this series, we had covered Look Up Tables in-depth and utilized them to create some interesting lighting effects on images/videos. Now in this one, we are gonna level up the game by creating 10 very interesting and cool Instagram filters.
The Filters which are gonna be covered are; Warm Filter, Cold Filter, Gotham Filter, GrayScale Filter, Sepia Filter, Pencil Sketch Filter, Sharpening Filter, Detail Enhancing Filter, Invert Filter, and Stylization Filter.
You must have used at least one of these and maybe have wondered how these are created, what’s the magic (math) behind these. We are gonna cover all this in-depth in today’s tutorial and you will learn a ton of cool image transformation techniques with OpenCV so buckle up and keep reading the tutorial.
This is the last tutorial of our 3 part Creating Instagram Filters series. All three posts are titled as:
Part 3: Designing Advanced Image Filters in OpenCV (Current tutorial)
3-4 Filters in this tutorial use Look Up Tables (LUT) which were explained in the previous tutorial, so make sure to go over that one if you haven’t already. Also, we have used mouse events to switch between filters in real-time and had covered mouse events in the first post of the series, so go over that tutorial as well if you don’t know how to use mouse events in OpenCV.
The tutorial is pretty simple and straightforward, but for a detailed explanation you can check out the YouTube video above, although this blog post alone does have enough details to help you follow along.
We will start by importing the required libraries.
import cv2
import pygame
import numpy as np
import matplotlib.pyplot as plt
from scipy.interpolate import UnivariateSpline
Creating Warm Filter-like Effect
The first filter is gonna be the famous Warm Effect, it absorbs blue cast in images, often caused by electronic flash or outdoor shade, and improves skin tones. This gives a kind of warm look to images that’s why it is called the Warm Effect. To apply this to images and videos, we will create a function applyWarm() that will decrease the pixel intensities of the blue channel and increase the intensities of the red channel of an image/frame by utilizing Look Up tables ( that we learned about in the previous tutorial).
So first, we will have to construct the Look Up Tables required to increase/decrease pixel intensities. For this purpose, we will be using the scipy.interpolate.UnivariateSpline() function to get the required input-output mapping.
# Construct a lookuptable for increasing pixel values.
# We are giving y values for a set of x values.
# And calculating y for [0-255] x values accordingly to the given range.
increase_table = UnivariateSpline(x=[0, 64, 128, 255], y=[0, 75, 155, 255])(range(256))

# Similarly construct a lookuptable for decreasing pixel values.
decrease_table = UnivariateSpline(x=[0, 64, 128, 255], y=[0, 45, 95, 255])(range(256))

# Display the first 10 mappings from the constructed tables.
print(f'First 10 elements from the increase table: \n {increase_table[:10]}\n')
print(f'First 10 elements from the decrease table:: \n {decrease_table[:10]}')
Output:
First 10 elements from the increase table: [7.32204295e-15 1.03827895e+00 2.08227359e+00 3.13191257e+00 4.18712454e+00 5.24783816e+00 6.31398207e+00 7.38548493e+00 8.46227539e+00 9.54428209e+00]
First 10 elements from the decrease table:: [-5.69492230e-15 7.24142824e-01 1.44669675e+00 2.16770636e+00 2.88721627e+00 3.60527107e+00 4.32191535e+00 5.03719372e+00 5.75115076e+00 6.46383109e+00]
Now that we have the Look Up Tables we need, we can move on to transforming the red and blue channel of the image/frame using the function cv2.LUT(). And to split and merge the channels of the image/frame, we will be using the function cv2.split() and cv2.merge() respectively. The applyWarm() function (like every other function in this tutorial) will display the resultant image along with the original image or return the resultant image depending upon the passed arguments.
def applyWarm(image, display=True):
    '''
    This function will create instagram Warm filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Warm filter applied.
    '''

    # Split the blue, green, and red channel of the image.
    blue_channel, green_channel, red_channel  = cv2.split(image)

    # Increase red channel intensity using the constructed lookuptable.
    red_channel = cv2.LUT(red_channel, increase_table).astype(np.uint8)

    # Decrease blue channel intensity using the constructed lookuptable.
    blue_channel = cv2.LUT(blue_channel, decrease_table).astype(np.uint8)

    # Merge the blue, green, and red channel.
    output_image = cv2.merge((blue_channel, green_channel, red_channel))

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now, let’s utilize the applyWarm() function created above to apply this warm filter on a few sample images.
# Read a sample image and apply Warm filter on it.
image = cv2.imread('media/sample1.jpg')
applyWarm(image)
# Read another sample image and apply Warm filter on it.
image = cv2.imread('media/sample2.jpg')
applyWarm(image)
Woah! Got the same results as the Instagram warm filter, with just a few lines of code. Now let’s move on to the next one.
Creating Cold Filter-like Effect
This one is kind of the opposite of the above filter, it gives coldness look to images/videos by increasing the blue cast. To create this filter effect, we will define a function applyCold() that will increase the pixel intensities of the blue channel and decrease the intensities of the red channel of an image/frame by utilizing the same LookUp tables, we had constructed above.
For this one too, we will be using the cv2.split(), cv2.LUT() and cv2.merge() functions to split, transform, and merge the channels.
def applyCold(image, display=True):
    '''
    This function will create instagram Cold filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Cold filter applied.
    '''

    # Split the blue, green, and red channel of the image.
    blue_channel, green_channel, red_channel = cv2.split(image)

    # Decrease red channel intensity using the constructed lookuptable.
    red_channel = cv2.LUT(red_channel, decrease_table).astype(np.uint8)

    # Increase blue channel intensity using the constructed lookuptable.
    blue_channel = cv2.LUT(blue_channel, increase_table).astype(np.uint8)

    # Merge the blue, green, and red channel.
    output_image = cv2.merge((blue_channel, green_channel, red_channel))

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now we will test this cold filter effect utilizing the applyCold() function on some sample images.
# Read a sample image and apply cold filter on it.
image = cv2.imread('media/sample3.jpg')
applyCold(image)
# Read another sample image and apply cold filter on it.
image = cv2.imread('media/sample4.jpg')
applyCold(image)
Now we’ll use the look up table creat
Nice! Got the expected results for this one too.
Creating Gotham Filter-like Effect
Now the famous Gotham Filter comes in, you must have heard or used this one on Instagram, it gives a warm reddish type look to images. We will try to apply a similar effect to images and videos by creating a function applyGotham(), that will utilize LookUp tables to manipulate image/frame channels in the following manner.
Increase mid-tone contrast of the red channel
Boost the lower-mid values of the blue channel
Decrease the upper-mid values of the blue channel
But again first, we will have to construct the Look Up Tables required to perform the manipulation on the red and blue channels of the image. We will again utilize the scipy.interpolate.UnivariateSpline() function to get the required mapping.
# Construct a lookuptable for increasing midtone contrast.
# Meaning this table will decrease the difference between the midtone values.
# Again we are giving Ys for some Xs and calculating for the remaining ones ([0-255] by using range(256)).
midtone_contrast_increase = UnivariateSpline(x=[0, 25, 51, 76, 102, 128, 153, 178, 204, 229, 255],
                                             y=[0, 13, 25, 51, 76, 128, 178, 204, 229, 242, 255])(range(256))

# Construct a lookuptable for increasing lowermid pixel values.
lowermids_increase = UnivariateSpline(x=[0, 16, 32, 48, 64, 80, 96, 111, 128, 143, 159, 175, 191, 207, 223, 239, 255],
                                      y=[0, 18, 35, 64, 81, 99, 107, 112, 121, 143, 159, 175, 191, 207, 223, 239, 255])(range(256))

# Construct a lookuptable for decreasing uppermid pixel values.
uppermids_decrease = UnivariateSpline(x=[0, 16, 32, 48, 64, 80, 96, 111, 128, 143, 159, 175, 191, 207, 223, 239, 255],
                                      y=[0, 16, 32, 48, 64, 80, 96, 111, 128, 140, 148, 160, 171, 187, 216, 236, 255])(range(256))

# Display the first 10 mappings from the constructed tables.
print(f'First 10 elements from the midtone contrast increase table: \n {midtone_contrast_increase[:10]}\n')
print(f'First 10 elements from the lowermids increase table: \n {lowermids_increase[:10]}\n')
print(f'First 10 elements from the uppermids decrease table:: \n {uppermids_decrease[:10]}')
First 10 elements from the midtone contrast increase table: [0.09416024 0.75724879 1.39938782 2.02149343 2.62448172 3.20926878 3.77677071 4.32790362 4.8635836 5.38472674]
First 10 elements from the lowermids increase table: [0.15030475 1.31080448 2.44957754 3.56865611 4.67007234 5.75585842 6.82804653 7.88866883 8.9397575 9.98334471]
First 10 elements from the uppermids decrease table:: [-0.27440589 0.8349419 1.93606131 3.02916902 4.11448171 5.19221607 6.26258878 7.32581654 8.38211602 9.4317039 ]
Now that we have the required mappings, we can move on to creating the function applyGotham() that will utilize these LookUp tables to apply the required effect.
def applyGotham(image, display=True):
    '''
    This function will create instagram Gotham filter like effect on an image.
    Args:
        image:   The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Gotham filter applied.
    '''

    # Split the blue, green, and red channel of the image.
    blue_channel, green_channel, red_channel = cv2.split(image)

    # Boost the mid-tone red channel contrast using the constructed lookuptable.
    red_channel = cv2.LUT(red_channel, midtone_contrast_increase).astype(np.uint8)

    # Boost the Blue channel in lower-mids using the constructed lookuptable.
    blue_channel = cv2.LUT(blue_channel, lowermids_increase).astype(np.uint8)

    # Decrease the Blue channel in upper-mids using the constructed lookuptable.
    blue_channel = cv2.LUT(blue_channel, uppermids_decrease).astype(np.uint8)

    # Merge the blue, green, and red channel.
    output_image = cv2.merge((blue_channel, green_channel, red_channel))

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now, let’s test this Gotham effect utilizing the applyGotham() function on a few sample images and visualize the results.
# Read a sample image and apply Gotham filter on it.
image = cv2.imread('media/sample5.jpg')
applyGotham(image)
# Read another sample image and apply Gotham filter on it.
image = cv2.imread('media/sample6.jpg')
applyGotham(image)
Now w
Stunning results! Now, let’s move to a simple one.
Creating Grayscale Filter-like Effect
Instagram also has a Grayscale filter also known as 50s TV Effect, it simply converts a (RGB) color image into a Grayscale (black and white) image. We can easily create a similar effect in OpenCV by using the cv2.cvtColor() function. So let’s create a function applyGrayscale() that will utilize cv2.cvtColor() function to apply this Grayscale filter-like effect on images and videos.
def applyGrayscale(image, display=True):
    '''
    This function will create instagram Grayscale filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Grayscale filter applied.
    '''

    # Convert the image into the grayscale.
    gray = cv2.cvtColor(image, cv2.COLOR_BGR2GRAY)

    # Merge the grayscale (one-channel) image three times to make it a three-channel image.
    output_image = cv2.merge((gray, gray, gray))

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now let’s utilize this applyGrayscale() function to apply the grayscale effect on a few sample images and display the results.
# Read a sample image| and apply Grayscale filter on it.
image = cv2.imread('media/sample7.jpg')
applyGrayscale(image)
# Read another sample image and apply Grayscale filter on it.
image = cv2.imread('media/sample8.jpg')
applyGrayscale(image)
Cool! Working as expected. Let’s move on to the next one.
Creating Sepia Filter-like Effect
I think this one is the most famous among all the filters we are creating today. This gives a warm reddish-brown vintage effect to images which makes the images look a bit ancient which is really cool. To apply this effect, we will create a function applySepia() that will utilize the cv2.transform() function and the fixed sepia matrix (standardized to create this effect, that you can easily find online) to serve the purpose.
def applySepia(image, display=True):
    '''
    This function will create instagram Sepia filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Sepia filter applied.
    '''

    # Convert the image into float type to prevent loss during operations.
    image_float = np.array(image, dtype=np.float64)


    # Manually transform the image to get the idea of exactly whats happening.
    ##################################################################################################

    # Split the blue, green, and red channel of the image.
    blue_channel, green_channel, red_channel = cv2.split(image_float)

    # Apply the Sepia filter by perform the matrix multiplication between
    # the image and the sepia matrix.
    output_blue = (red_channel * .272) + (green_channel *.534) + (blue_channel * .131)
    output_green = (red_channel * .349) + (green_channel *.686) + (blue_channel * .168)
    output_red = (red_channel * .393) + (green_channel *.769) + (blue_channel * .189)

    # Merge the blue, green, and red channel.
    output_image = cv2.merge((output_blue, output_green, output_red))

    ##################################################################################################


        # OR Either create this effect by using OpenCV matrix transformation function.
    ##################################################################################################

    # Get the sepia matrix for BGR colorspace images.
    sepia_matrix = np.matrix([[.272, .534, .131],
                              [.349, .686, .168],
                              [.393, .769, .189]])

    # Apply the Sepia filter by perform the matrix multiplication between
    # the image and the sepia matrix.
    #output_image = cv2.transform(src=image_float, m=sepia_matrix)

    ##################################################################################################


    # Set the values > 255 to 255.
    output_image[output_image > 255] = 255

    # Convert the image back to uint8 type.
    output_image =  np.array(output_image, dtype=np.uint8)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now let’s check this sepia effect by utilizing the applySepia() function on a few sample images.
# Read a sample image and apply Sepia filter on it.
image = cv2.imread('media/sample9.jpg')
applySepia(image)
# Read another sample image and apply Sepia filter on it.
image = cv2.imread('media/sample18.jpg')
applySepia(image)
Spectacular results! Reminds me of the movies, I used to watch in my childhood ( Yes, I am that old 😜 ).
Creating Pencil Sketch Filter-like Effect
The next one is the Pencil Sketch Filter, creating a Pencil Sketch manually requires hours of hard work but luckily in OpenCV, we can do this in just one line of code by using the function cv2.pencilSketch() that give a pencil sketch-like effect to images. So lets create a function applyPencilSketch() to convert images/videos into Pencil Sketches utilizing the cv2.pencilSketch() function.
We will use the following funciton to applythe pencil sketch filter, this function retruns a grayscale sketch and a colored sketch of the image
This filter is a type of edge preserving filter, these filters have 2 Objectives, one is to give more weightage to pixels closer so that the blurring can be meaningfull and second to average only the similar intensity valued pixels to avoid the edges, so in this both of these objectives are controled by the two following parameters.
sigma_s Just like sigma in other smoothing filters this sigma value controls the area of the neighbourhood (Has Range between 0-200)
sigma_r This param controls the how dissimilar colors within the neighborhood will be averaged. For example a larger value will restrcit color variation and it will enforce that constant color stays throughout. (Has Range between 0-1)
shade_factor This has range 0-0.1 and controls how bright the final output will be by scaling the intensity.
def applyPencilSketch(image, display=True):
    '''
    This function will create instagram Pencil Sketch filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Pencil Sketch filter applied.
    '''

    # Apply Pencil Sketch effect on the image.
    gray_sketch, color_sketch = cv2.pencilSketch(image, sigma_s=20, sigma_r=0.5, shade_factor=0.02)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(131);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(132);plt.imshow(color_sketch[:,:,::-1]);plt.title("ColorSketch Image");plt.axis('off');
        plt.subplot(133);plt.imshow(gray_sketch, cmap='gray');plt.title("GraySketch Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return color_sketch
Now we will apply this pencil sketch effect by utilizing the applyPencilSketch() function on a few sample images and visualize the results.
# Read a sample image and apply PencilSketch filter on it.
image = cv2.imread('media/sample11.jpg')
applyPencilSketch(image)
Now let’s check how the changeIntensity() functi
# Read another sample image and apply PencilSketch filter on it.
image = cv2.imread('media/sample5.jpg')
applyPencilSketch(image)
Amazing right? we created this effect with just a single line of code. So now, instead of spending hours manually sketching someone or something, you can take an image and apply this effect on it to get the results in seconds. And you can further tune the parameters of the cv2.pencilSketch() function to get even better results.
Creating Sharpening Filter-like Effect
Now let’s try to create the Sharpening Effect, this enhances the clearness of an image/video and decreases the blurriness which gives a new interesting look to the image/video. For this we will create a function applySharpening() that will utilize the cv2.filter2D() function to give the required effect to an image/frame passed to it.
 def applySharpening(image, display=True):
    '''
    This function will create the Sharpening filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Sharpening filter applied.
    '''

    # Get the kernel required for the sharpening effect.
    sharpening_kernel = np.array([[-1, -1, -1],
                                  [-1, 9.2, -1],
                                  [-1, -1, -1]])

    # Apply the sharpening filter on the image.
    output_image = cv2.filter2D(src=image, ddepth=-1,
                                kernel=sharpening_kernel)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now, let’s see this in action utilizing the applySharpening() function created above on a few sample images.
# Read a sample image and apply Sharpening filter on it.
image = cv2.imread('media/sample12.jpg')
applySharpening(image)
# Read another sample image and apply Sharpening filter on it.
image = cv2.imread('media/sample13.jpg')
applySharpening(image)
Nice! this filter makes the original images look as if they are out of focus (blur).
Creating a Detail Enhancing Filter
Now this Filter is another type of edge preserving fitler and has the same parameters as the pencil sketch filter.This filter intensifies the details in images/videos, we’ll be using the function called cv2.detailEnhance(). let’s start by creating the a wrapper function applyDetailEnhancing(), that will utilize the cv2.detailEnhance() function to apply the needed effect.
def applyDetailEnhancing(image, display=True):
    '''
    This function will create the HDR filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the HDR filter applied.
    '''

    # Apply the detail enhancing effect by enhancing the details of the image.
    output_image = cv2.detailEnhance(image, sigma_s=15, sigma_r=0.15)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now, let’s test the function applyDetailEnhancing() created above on a few sample images.
# Read a sample image and apply Detail Enhancing filter on it.
image = cv2.imread('media/sample14.jpg')
applyDetailEnhancing(image)
# Read another sample image and apply Detail Enhancing filter on it.
image = cv2.imread('media/sample15.jpg')
applyDetailEnhancing(image)
Satisfying results! let’s move on to the next one.
Creating Invert Filter-like Effect
This filter inverts the colors in images/videos meaning changes darkish colors into light and vice versa, which gives a very interesting look to images/videos. This can be accomplished using multiple approaches we can either utilize a LookUp table to perform the required transformation or subtract the image by 255 and take absolute of the results or just simply use the OpenCV function cv2.bitwise_not(). Let’s create a function applyInvert() to serve the purpose.
def applyInvert(image, display=True):
    '''
    This function will create the Invert filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the Invert filter applied.
    '''

    # Apply the Invert Filter on the image.
    output_image = cv2.bitwise_not(image)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Let’s check this effect on a few sample images utilizing the applyInvert() function.
# Read a sample image and apply invert filter on it.
image = cv2.imread('media/sample16.jpg')
applyInvert(image)
Looks a little scary, lets’s try it on a few landscape images.
# Read a landscape image and apply invert filter on it.
image = cv2.imread('media/sample19.jpg')
applyInvert(image)
# Read another landscape image and apply invert filter on it.
image = cv2.imread('media/sample20.jpg')
applyInvert(image)
Interesting effect! but I will definitely not recommend using this one on your own images, except if your intention is to scare someone xD.
Creating Stylization Filter-like Effect
Now let’s move on to the final one, which gives a painting-like effect to images. We will create a function applyStylization() that will utilize the cv2.stylization() function to apply this effect on images and videos. This one too will only need a single line of code.
def applyStylization(image, display=True):
    '''
    This function will create instagram cartoon-paint filter like effect on an image.
    Args:
        image:  The image on which the filter is to be applied.
        display: A boolean value that is if set to true the function displays the original image,
                 and the output image, and returns nothing.
    Returns:
        output_image: A copy of the input image with the cartoon-paint filter applied.
    '''

    # Apply stylization effect on the image.
    output_image = cv2.stylization(image, sigma_s=15, sigma_r=0.55)

    # Check if the original input image and the output image are specified to be displayed.
    if display:

        # Display the original input image and the output image.
        plt.figure(figsize=[15,15])
        plt.subplot(121);plt.imshow(image[:,:,::-1]);plt.title("Input Image");plt.axis('off');
        plt.subplot(122);plt.imshow(output_image[:,:,::-1]);plt.title("Output Image");plt.axis('off');

    # Otherwise.
    else:

        # Return the output image.
        return output_image
Now, as done for every other filter, we will utilize the function applyStylization() to test this effect on a few sample images.
# Read a sample image and apply Stylization filter on it.
image = cv2.imread('media/sample16.jpg')
applyStylization(image)
# Read another sample image and apply Stylization filter on it.
image = cv2.imread('media/sample17.jpg')
applyStylization(image)
Again got fascinating results! Wasn’t that fun to see how simple it is to create all these effects?
Apply Instagram Filters On a Real-Time Web-cam Feed
Now that we have created the filters and have tested them on images, let’s move to apply these on a real-time webcam feed, first, we will have to create a mouse event callback function mouseCallback(), similar to the one we had created for the Color Filters in the previous tutorial, the function will allow us to select the filter to apply, and capture and store images into the disk by utilizing mouse events in real-time.
def mouseCallback(event, x, y, flags, userdata):
    '''
    This function will update the filter to apply on the frame and capture images based on different mouse events.
    Args:
        event:    The mouse event that is captured.
        x:        The x-coordinate of the mouse pointer position on the window.
        y:        The y-coordinate of the mouse pointer position on the window.
        flags:    It is one of the MouseEventFlags constants.
        userdata: The parameter passed from the `cv2.setMouseCallback()` function.
    '''
    #  Access the filter applied, and capture image state variable.
    global filter_applied, capture_image

    # Check if the left mouse button is pressed.
    if event == cv2.EVENT_LBUTTONDOWN:

        # Check if the mouse pointer is over the camera icon ROI.
        if y >= (frame_height-10)-camera_icon_height and \
        x >= (frame_width//2-camera_icon_width//2) and \
        x <= (frame_width//2+camera_icon_width//2):

            # Update the image capture state to True.
            capture_image = True

        # Check if the mouse pointer y-coordinate is over the filters ROI.
        elif y <= 10+preview_height:

            # Check if the mouse pointer x-coordinate is over the Warm filter ROI.
            if x>(int(frame_width//11.6)-preview_width//2) and \
            x<(int(frame_width//11.6)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Warm.
                filter_applied = 'Warm'

            # Check if the mouse pointer x-coordinate is over the Cold filter ROI.
            elif x>(int(frame_width//5.9)-preview_width//2) and \
            x<(int(frame_width//5.9)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Cold.
                filter_applied = 'Cold'

            # Check if the mouse pointer x-coordinate is over the Gotham filter ROI.
            elif x>(int(frame_width//3.97)-preview_width//2) and \
            x<(int(frame_width//3.97)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Gotham.
                filter_applied = 'Gotham'

            # Check if the mouse pointer x-coordinate is over the Grayscale filter ROI.
            elif x>(int(frame_width//2.99)-preview_width//2) and \
            x<(int(frame_width//2.99)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Grayscale.
                filter_applied = 'Grayscale'

            # Check if the mouse pointer x-coordinate is over the Sepia filter ROI.
            elif x>(int(frame_width//2.395)-preview_width//2) and \
            x<(int(frame_width//2.395)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Sepia.
                filter_applied = 'Sepia'

            # Check if the mouse pointer x-coordinate is over the Normal filter ROI.
            elif x>(int(frame_width//2)-preview_width//2) and \
            x<(int(frame_width//2)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Normal.
                filter_applied = 'Normal'

            # Check if the mouse pointer x-coordinate is over the Pencil Sketch filter ROI.
            elif x>(frame_width//1.715-preview_width//2) and \
            x<(frame_width//1.715-preview_width//2)+preview_width:

                # Update the filter applied variable value to Pencil Sketch.
                filter_applied = 'Pencil Sketch'

            # Check if the mouse pointer x-coordinate is over the Sharpening filter ROI.
            elif x>(int(frame_width//1.501)-preview_width//2) and \
            x<(int(frame_width//1.501)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Sharpening.
                filter_applied = 'Sharpening'

            # Check if the mouse pointer x-coordinate is over the Invert filter ROI.
            elif x>(int(frame_width//1.335)-preview_width//2) and \
            x<(int(frame_width//1.335)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Invert.
                filter_applied = 'Invert'

            # Check if the mouse pointer x-coordinate is over the Detail Enhancing filter ROI.
            elif x>(int(frame_width//1.202)-preview_width//2) and \
            x<(int(frame_width//1.202)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Detail Enhancing.
                filter_applied = 'Detail Enhancing'

            # Check if the mouse pointer x-coordinate is over the Stylization filter ROI.
            elif x>(int(frame_width//1.094)-preview_width//2) and \
            x<(int(frame_width//1.094)-preview_width//2)+preview_width:

                # Update the filter applied variable value to Stylization.
                filter_applied = 'Stylization'
Now that we have a mouse event callback function mouseCallback() to select a filter to apply, we will create another function applySelectedFilter() that we will need, to check which filter is selected at the moment and apply that filter to the image/frame in real-time.
def applySelectedFilter(image, filter_applied):
    '''
    This function will apply the selected filter on an image.
    Args:
        image:          The image on which the selected filter is to be applied.
        filter_applied: The name of the filter selected by the user.
    Returns:
        output_image: A copy of the input image with the selected filter applied.
    '''

    # Check if the specified filter to apply, is the Warm filter.
    if filter_applied == 'Warm':

        # Apply the Warm Filter on the image.
        output_image = applyWarm(image, display=False)

    # Check if the specified filter to apply, is the Cold filter.
    elif filter_applied == 'Cold':

        # Apply the Cold Filter on the image.
        output_image = applyCold(image, display=False)

    # Check if the specified filter to apply, is the Gotham filter.
    elif filter_applied == 'Gotham':

        # Apply the Gotham Filter on the image.
        output_image = applyGotham(image, display=False)

     # Check if the specified filter to apply, is the Grayscale filter.
    elif filter_applied == 'Grayscale':

        # Apply the Grayscale Filter on the image.
        output_image = applyGrayscale(image, display=False)

    # Check if the specified filter to apply, is the Sepia filter.
    if filter_applied == 'Sepia':

        # Apply the Sepia Filter on the image.
        output_image = applySepia(image, display=False)

    # Check if the specified filter to apply, is the Pencil Sketch filter.
    elif filter_applied == 'Pencil Sketch':

        # Apply the Pencil Sketch Filter on the image.
        output_image = applyPencilSketch(image, display=False)

    # Check if the specified filter to apply, is the Sharpening filter.
    elif filter_applied == 'Sharpening':

        # Apply the Sharpening Filter on the image.
        output_image = applySharpening(image, display=False)

    # Check if the specified filter to apply, is the Invert filter.
    elif filter_applied == 'Invert':

        # Apply the Invert Filter on the image.
        output_image = applyInvert(image, display=False)

    # Check if the specified filter to apply, is the Detail Enhancing filter.
    elif filter_applied == 'Detail Enhancing':

        # Apply the Detail Enhancing Filter on the image.
        output_image = applyDetailEnhancing(image, display=False)

    # Check if the specified filter to apply, is the Stylization filter.
    elif filter_applied == 'Stylization':

        # Apply the Stylization Filter on the image.
        output_image = applyStylization(image, display=False)

    # Return the image with the selected filter applied.`
    return output_image
Now that we will the required functions, let’s test the filters on a real-time webcam feed, we will be switching between the filters by utilizing the mouseCallback() and applySelectedFilter() functions created above and will overlay a Camera ROI over the frame and allow the user to capture images with the selected filter applied, by clicking on the Camera ROI in real-time.
# Initialize the VideoCapture object to read from the webcam.
camera_video = cv2.VideoCapture(1, cv2.CAP_DSHOW)
camera_video.set(3,1280)
camera_video.set(4,960)

# Create a named resizable window.
cv2.namedWindow('Instagram Filters', cv2.WINDOW_NORMAL)

# Attach the mouse callback function to the window.
cv2.setMouseCallback('Instagram Filters', mouseCallback)

# Initialize a variable to store the current applied filter.
filter_applied = 'Normal'

# Initialize a variable to store the copies of the frame
# with the filters applied.
filters = None

# Initialize the pygame modules and load the image-capture music file.
pygame.init()
pygame.mixer.music.load("media/camerasound.mp3")

# Initialize a variable to store the image capture state.
capture_image = False

# Initialize a variable to store a camera icon image.
camera_icon = None

# Iterate until the webcam is accessed successfully.
while camera_video.isOpened():

    # Read a frame.
    ok, frame = camera_video.read()

    # Check if frame is not read properly then
    # continue to the next iteration to read the next frame.
    if not ok:
        continue

    # Get the height and width of the frame of the webcam video.
    frame_height, frame_width, _ = frame.shape

    # Flip the frame horizontally for natural (selfie-view) visualization.
    frame = cv2.flip(frame, 1)

    # Check if the filters variable doesnot contain the filters.
    if not(filters):

        # Update the filters variable to store a dictionary containing multiple
        # copies of the frame with all the filters applied.
        filters = {'Normal': frame.copy(), 'Warm' : applyWarm(frame, display=False),
                   'Cold'  :applyCold(frame, display=False),
                   'Gotham' : applyGotham(frame, display=False),
                   'Grayscale' : applyGrayscale(frame, display=False),
                   'Sepia' : applySepia(frame, display=False),
                   'Pencil Sketch' : applyPencilSketch(frame, display=False),
                   'Sharpening': applySharpening(frame, display=False),
                   'Invert': applyInvert(frame, display=False),
                   'Detail Enhancing': applyDetailEnhancing(frame, display=False),
                   'Stylization': applyStylization(frame, display=False)}

    # Initialize a list to store the previews of the filters.
    filters_previews = []

    # Iterate over the filters dictionary.
    for filter_name, filtered_frame in filters.items():

        # Check if the filter we are iterating upon, is applied.
        if filter_applied == filter_name:

            # Set color to green.
            # This will be the border color of the filter preview.
            # And will be green for the filter applied and white for the other filters.
            color = (0,255,0)

        # Otherwise.
        else:

            # Set color to white.
            color = (255,255,255)

        # Make a border around the filter we are iterating upon.
        filter_preview = cv2.copyMakeBorder(src=filtered_frame, top=100, bottom=100,
                                            left=10, right=10, borderType=cv2.BORDER_CONSTANT,
                                            value=color)

        # Resize the preview to the 1/12th of its current width and height.
        filter_preview = cv2.resize(filter_preview, (frame_width//12,frame_height//12))

        # Append the filter preview into the list.
        filters_previews.append(filter_preview)

    # Get the new height and width of the previews.
    preview_height, preview_width, _ = filters_previews[0].shape

    # Check if any filter is selected.
    if filter_applied != 'Normal':

        # Apply the selected Filter on the frame.
        frame = applySelectedFilter(frame, filter_applied)

     # Check if the image capture state is True.
    if capture_image:

        # Capture an image and store it in the disk.
        cv2.imwrite('Captured_Image.png', frame)

        # Display a black image.
        cv2.imshow('Instagram Filters', np.zeros((frame_height, frame_width)))

        # Play the image capture music to indicate that an image is captured and wait for 100 milliseconds.
        pygame.mixer.music.play()
        cv2.waitKey(100)

        # Display the captured image.
        plt.close();plt.figure(figsize=[10, 10])
        plt.imshow(frame[:,:,::-1]);plt.title("Captured Image");plt.axis('off');

        # Update the image capture state to False.
        capture_image = False

    # Check if the camera icon variable doesnot contain the camera icon image.
    if not(camera_icon):

        # Read a camera icon png image with its blue, green, red, and alpha channel.
        camera_iconBGRA = cv2.imread('media/cameraicon.png', cv2.IMREAD_UNCHANGED)

        # Resize the camera icon image to the 1/12th of the frame width,
        # while keeping the aspect ratio constant.
        camera_iconBGRA = cv2.resize(camera_iconBGRA,
                                     (frame_width//12,
                                      int(((frame_width//12)/camera_iconBGRA.shape[1])*camera_iconBGRA.shape[0])))

        # Get the new height and width of the camera icon image.
        camera_icon_height, camera_icon_width, _ = camera_iconBGRA.shape

        # Get the first three-channels (BGR) of the camera icon image.
        camera_iconBGR  = camera_iconBGRA[:,:,:-1]

        # Get the alpha channel of the camera icon.
        camera_icon_alpha =  camera_iconBGRA[:,:,-1]

    # Get the region of interest of the frame where the camera icon image will be placed.
    frame_roi = frame[(frame_height-10)-camera_icon_height: (frame_height-10),
                      (frame_width//2-camera_icon_width//2): \
                      (frame_width//2-camera_icon_width//2)+camera_icon_width]

    # Overlay the camera icon over the frame by updating the pixel values of the frame
    # at the indexes where the alpha channel of the camera icon image has the value 255.
    frame_roi[camera_icon_alpha==255] = camera_iconBGR[camera_icon_alpha==255]

    # Overlay the resized preview filter images over the frame by updating
    # its pixel values in the region of interest.
    #######################################################################################

    # Overlay the Warm Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//11.6)-preview_width//2): \
          (int(frame_width//11.6)-preview_width//2)+preview_width] = filters_previews[1]

    # Overlay the Cold Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//5.9)-preview_width//2): \
          (int(frame_width//5.9)-preview_width//2)+preview_width] = filters_previews[2]

    # Overlay the Gotham Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//3.97)-preview_width//2): \
          (int(frame_width//3.97)-preview_width//2)+preview_width] = filters_previews[3]


    # Overlay the Grayscale Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//2.99)-preview_width//2): \
          (int(frame_width//2.99)-preview_width//2)+preview_width] = filters_previews[4]

    # Overlay the Sepia Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//2.395)-preview_width//2): \
          (int(frame_width//2.395)-preview_width//2)+preview_width] = filters_previews[5]

    # Overlay the Normal frame (no filter) preview on the frame.
    frame[10: 10+preview_height,
          (frame_width//2-preview_width//2): \
          (frame_width//2-preview_width//2)+preview_width] = filters_previews[0]

    # Overlay the Pencil Sketch Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.715)-preview_width//2): \
          (int(frame_width//1.715)-preview_width//2)+preview_width]=filters_previews[6]

    # Overlay the Sharpening Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.501)-preview_width//2): \
          (int(frame_width//1.501)-preview_width//2)+preview_width]=filters_previews[7]

    # Overlay the Invert Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.335)-preview_width//2): \
          (int(frame_width//1.335)-preview_width//2)+preview_width]=filters_previews[8]

    # Overlay the Detail Enhancing Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.202)-preview_width//2): \
          (int(frame_width//1.202)-preview_width//2)+preview_width]=filters_previews[9]

    # Overlay the Stylization Filter preview on the frame.
    frame[10: 10+preview_height,
          (int(frame_width//1.094)-preview_width//2): \
          (int(frame_width//1.094)-preview_width//2)+preview_width]=filters_previews[10]

    #######################################################################################

    # Display the frame.
    cv2.imshow('Instagram Filters', frame)

    # Wait for 1ms. If a key is pressed, retreive the ASCII code of the key.
    k = cv2.waitKey(1) & 0xFF

    # Check if 'ESC' is pressed and break the loop.
    if(k == 27):
        break

# Release the VideoCapture Object and close the windows.
camera_video.release()
cv2.destroyAllWindows()
Output Video:
Awesome! working as expected on the videos too.
Assignment (Optional)
Create your own Filter with an appropriate name by playing around with the techniques you have learned in this tutorial, and share the results with me in the comments section.
In today’s tutorial, we have covered several advanced image processing techniques and then utilized these concepts to create 10 different fascinating Instagram filters-like effects on images and videos.
This concludes the Creating Instagram Filters series, throughout the series we learned a ton of interesting concepts. In the first post, we learned all about using Mouse and TrackBars events in OpenCV, in the second post we learned to work with Lookup Tables in OpenCV and how to create color filters with it, and in this tutorial, we went even further and created more interesting color filters and other types of effects.
If you have found the series useful, do let me know in the comments section, I might publish some other very cool posts on image filters using deep learning. We also provide AI Consulting at Bleed AI Solutions, by building highly optimized and scalable bleeding-edge solutions for our clients so feel free to contact us if you have a problem or project that demands a cutting-edge AI/CV solution.